Tag: Security technology

  • MLEP in KICS for Networks 5.0: how machine learning helps track network behavior of OT devices

    MLEP in KICS for Networks 5.0: how machine learning helps track network behavior of OT devices

    In an industrial network, malicious activity can be hard to tell apart from normal data exchange between devices. Malicious actors routinely rely on legitimate tools and the Living-off-the-Land technique, so a single network connection may show no known signs of an attack: the device uses a familiar protocol and transmits ordinary data. An anomaly can hide in subtle details: the data source, the time of access, or the volume of transferred data may be atypical for a particular device. However, to detect this kind of anomaly, you need to understand the roles of the devices at both ends of the connection and know which network activity patterns are typical for them.

    But an organization’s asset inventory data is often incomplete, which makes it harder to catch unauthorized connections in time. Suppose monitoring detects a host that regularly exchanges data with programmable logic controllers (PLCs). Its IP address is known, but the inventory does not specify what role it plays: is it an engineering workstation, a process data server, or a piece of contractor’s equipment? The host may also have been on the industrial network for a long time, with its record going out of date after a network upgrade.

    In the joint OT asset inventory guidance released by CISA and its partners in 2025, inventorying devices and classifying them by role are treated as part of OT asset management. For organizations, this is one of the most important areas: according to the SANS 2025 ICS security survey, 50% of respondents had deployed or significantly expanded ICS inventory and visibility tools over the previous 12 months, and 54% named them as investment priorities for the next 12–24 months.

    Device inventory in Kaspersky Industrial CyberSecurity for Networks

    In Kaspersky Industrial CyberSecurity for Networks, the Asset Discovery technology is the foundation of asset visibility. Passive network traffic analysis detects devices and their interactions, while recognition rules help determine the device category and extract available information about it, such as the vendor, model, or software version. Exactly which attributes the system can obtain depends on the protocol and the traffic it observes. We covered this in more detail at the Kaspersky Industrial Cybersecurity Conference.
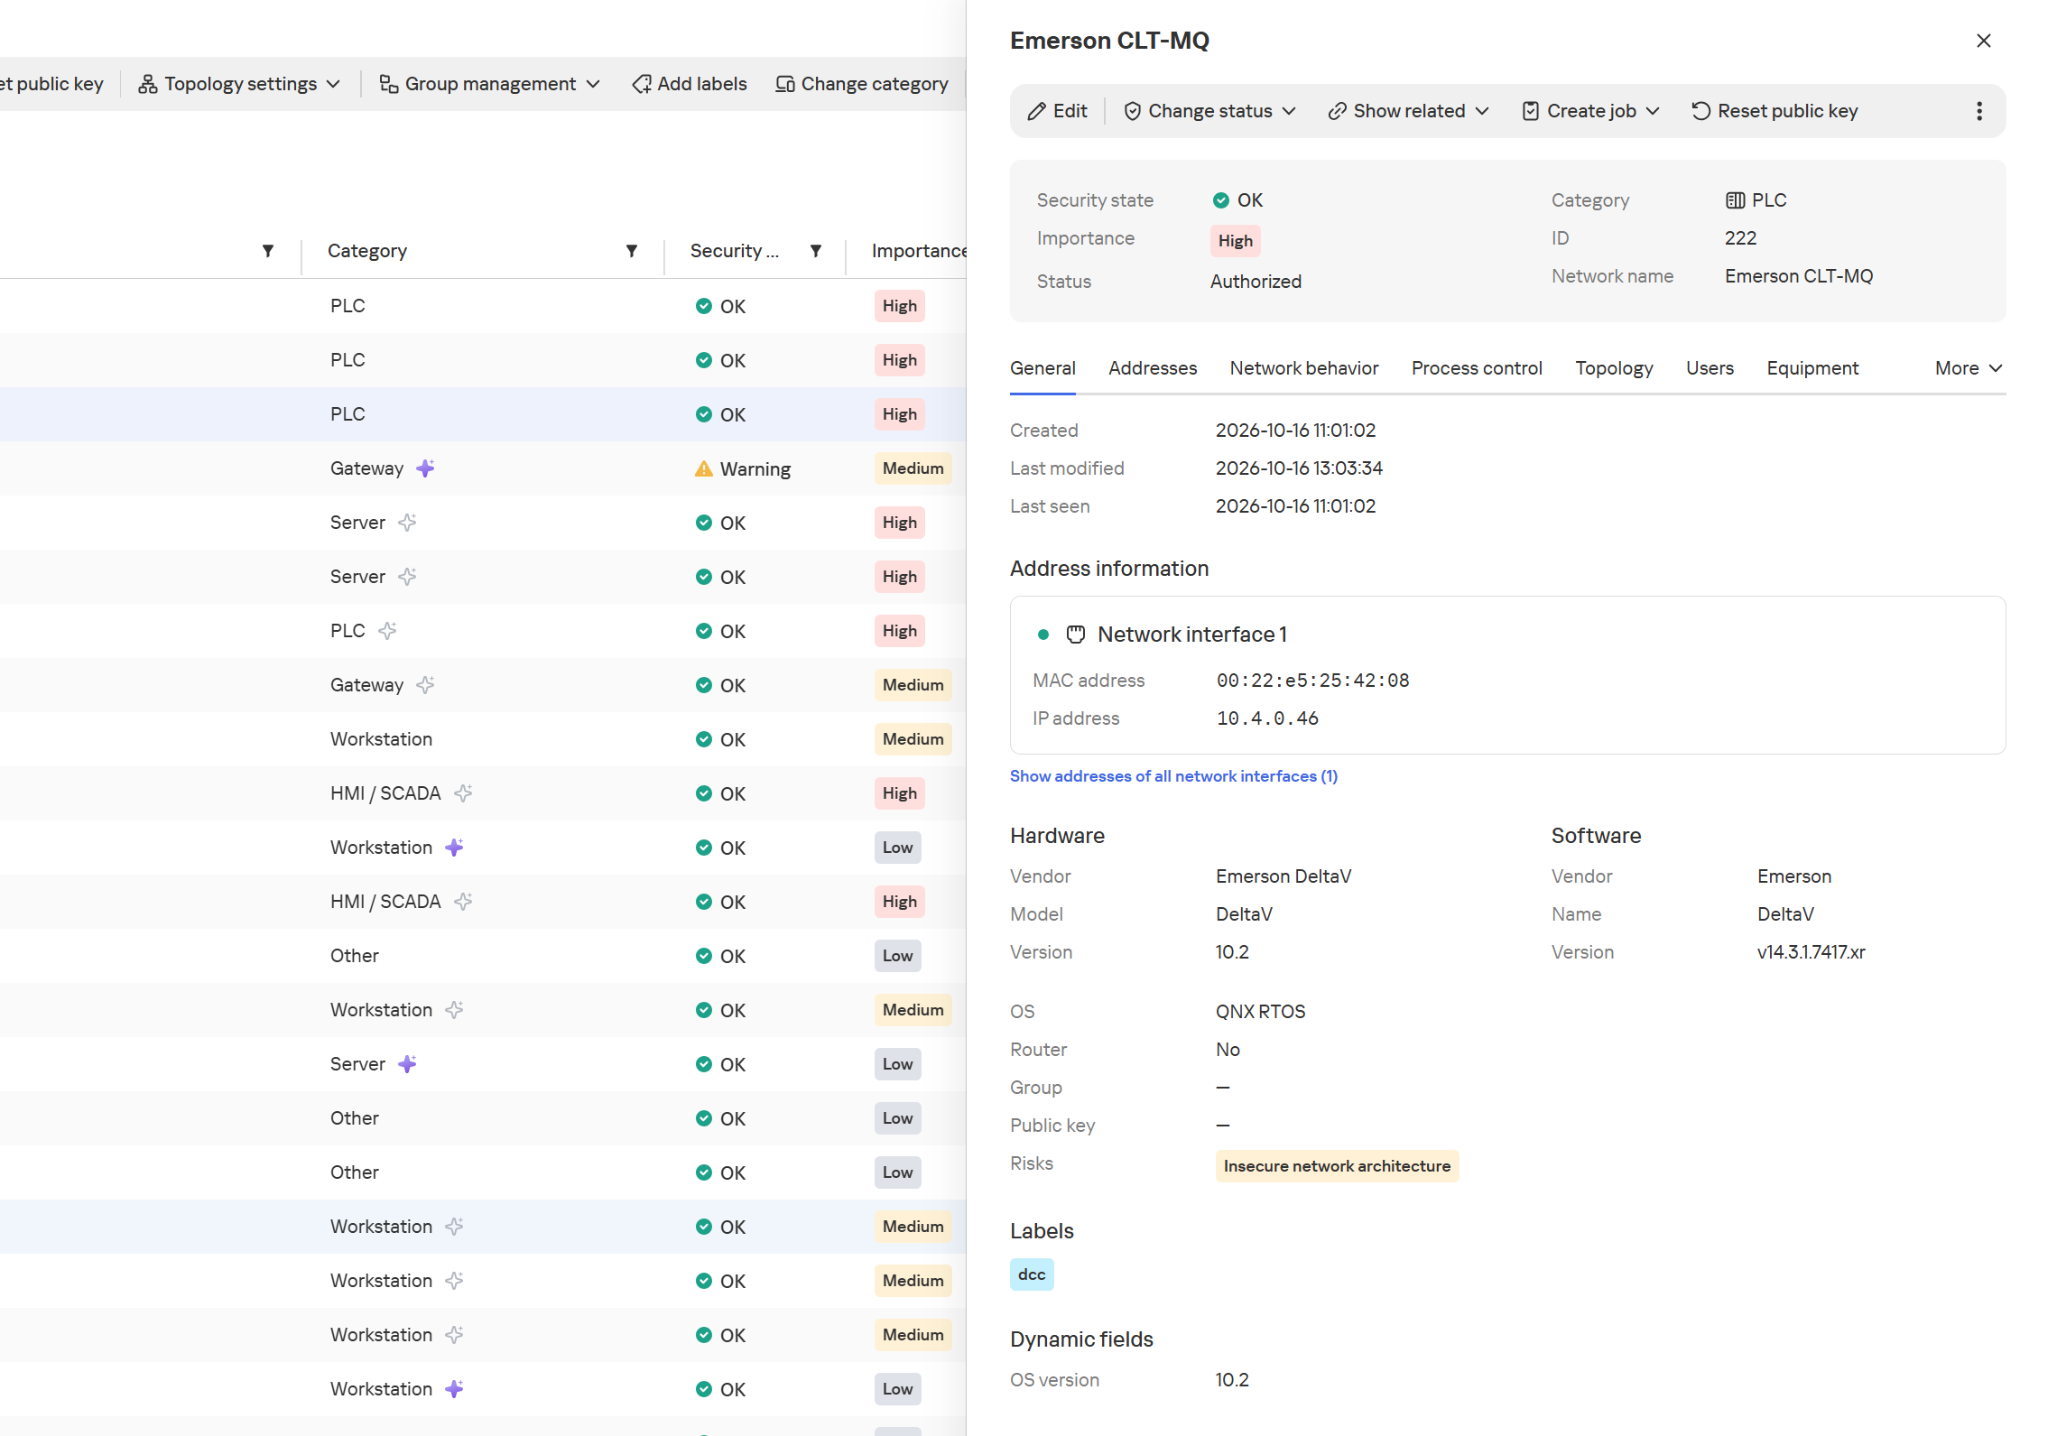
    Hardware and software information in the device card

    Hardware and software information in the device card

    The product also supports active polling modules (APMs): where polling is allowed, they can request additional configuration and firmware version details from devices. This kind of inventory is far more detailed than a list of IP addresses.
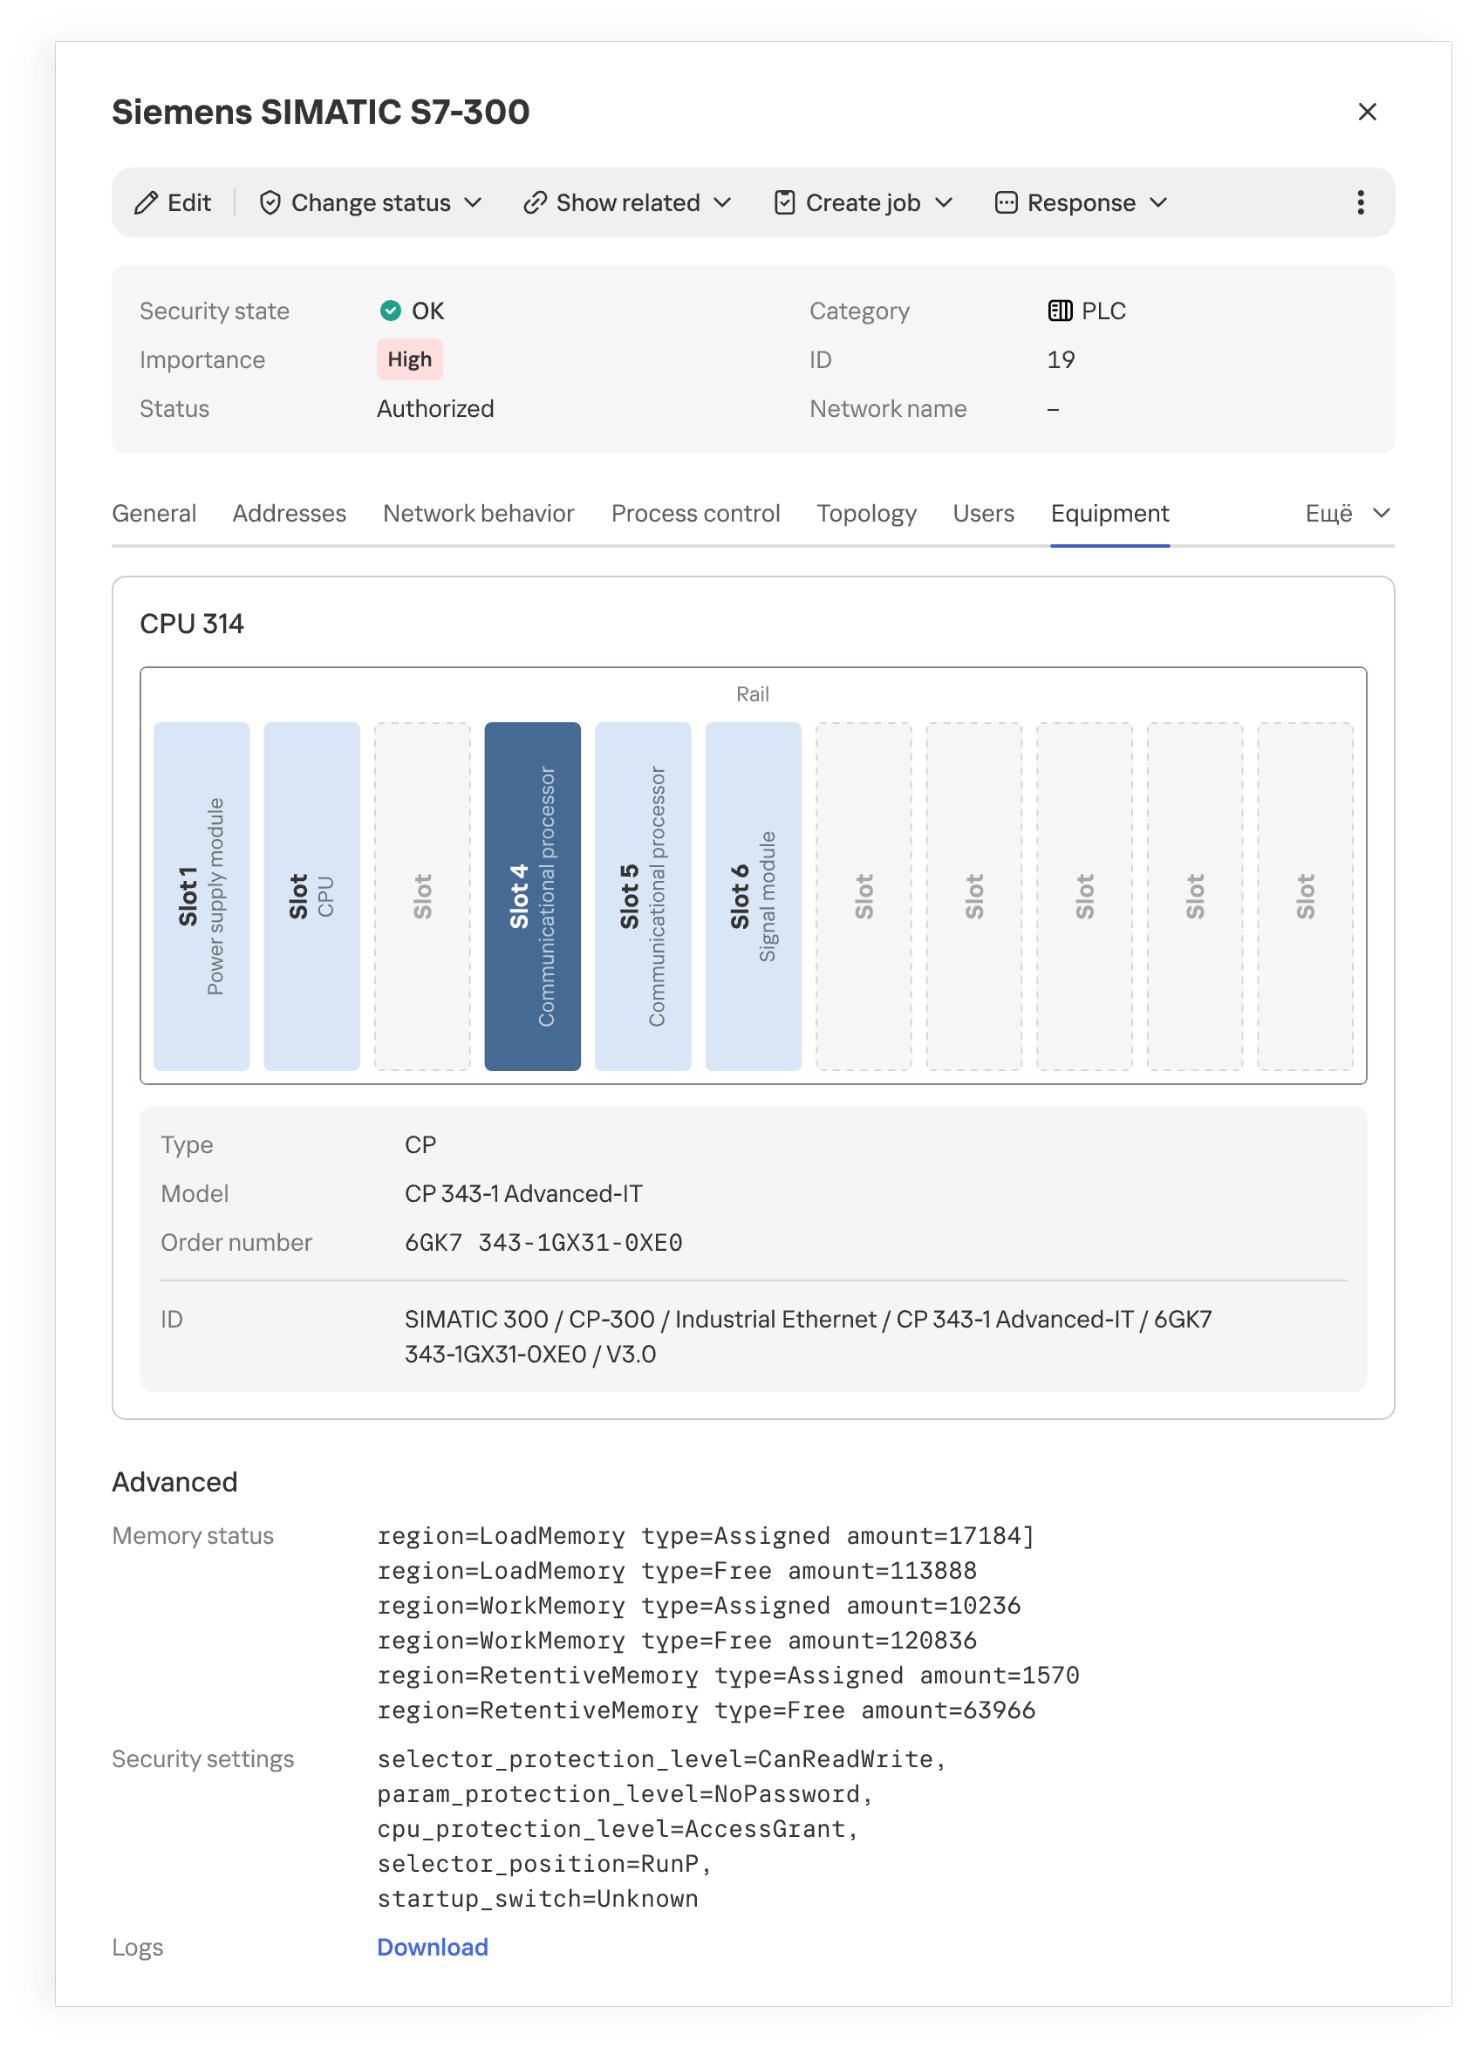
    Installed modules and their placement in a PLC rack

    Installed modules and their placement in a PLC rack

    However, even accurate hardware information doesn’t always explain what function a host performs in a specific industrial facility. Gaps appear for various reasons. Some devices send identifying information only at startup or during configuration, while others rarely communicate. Proprietary protocols can’t always be parsed, and encryption may leave only connection metadata for analysis. If the monitoring system doesn’t receive traffic from every segment of the industrial network, some network activity goes unobserved. Active polling doesn’t suit every device or every operating condition.
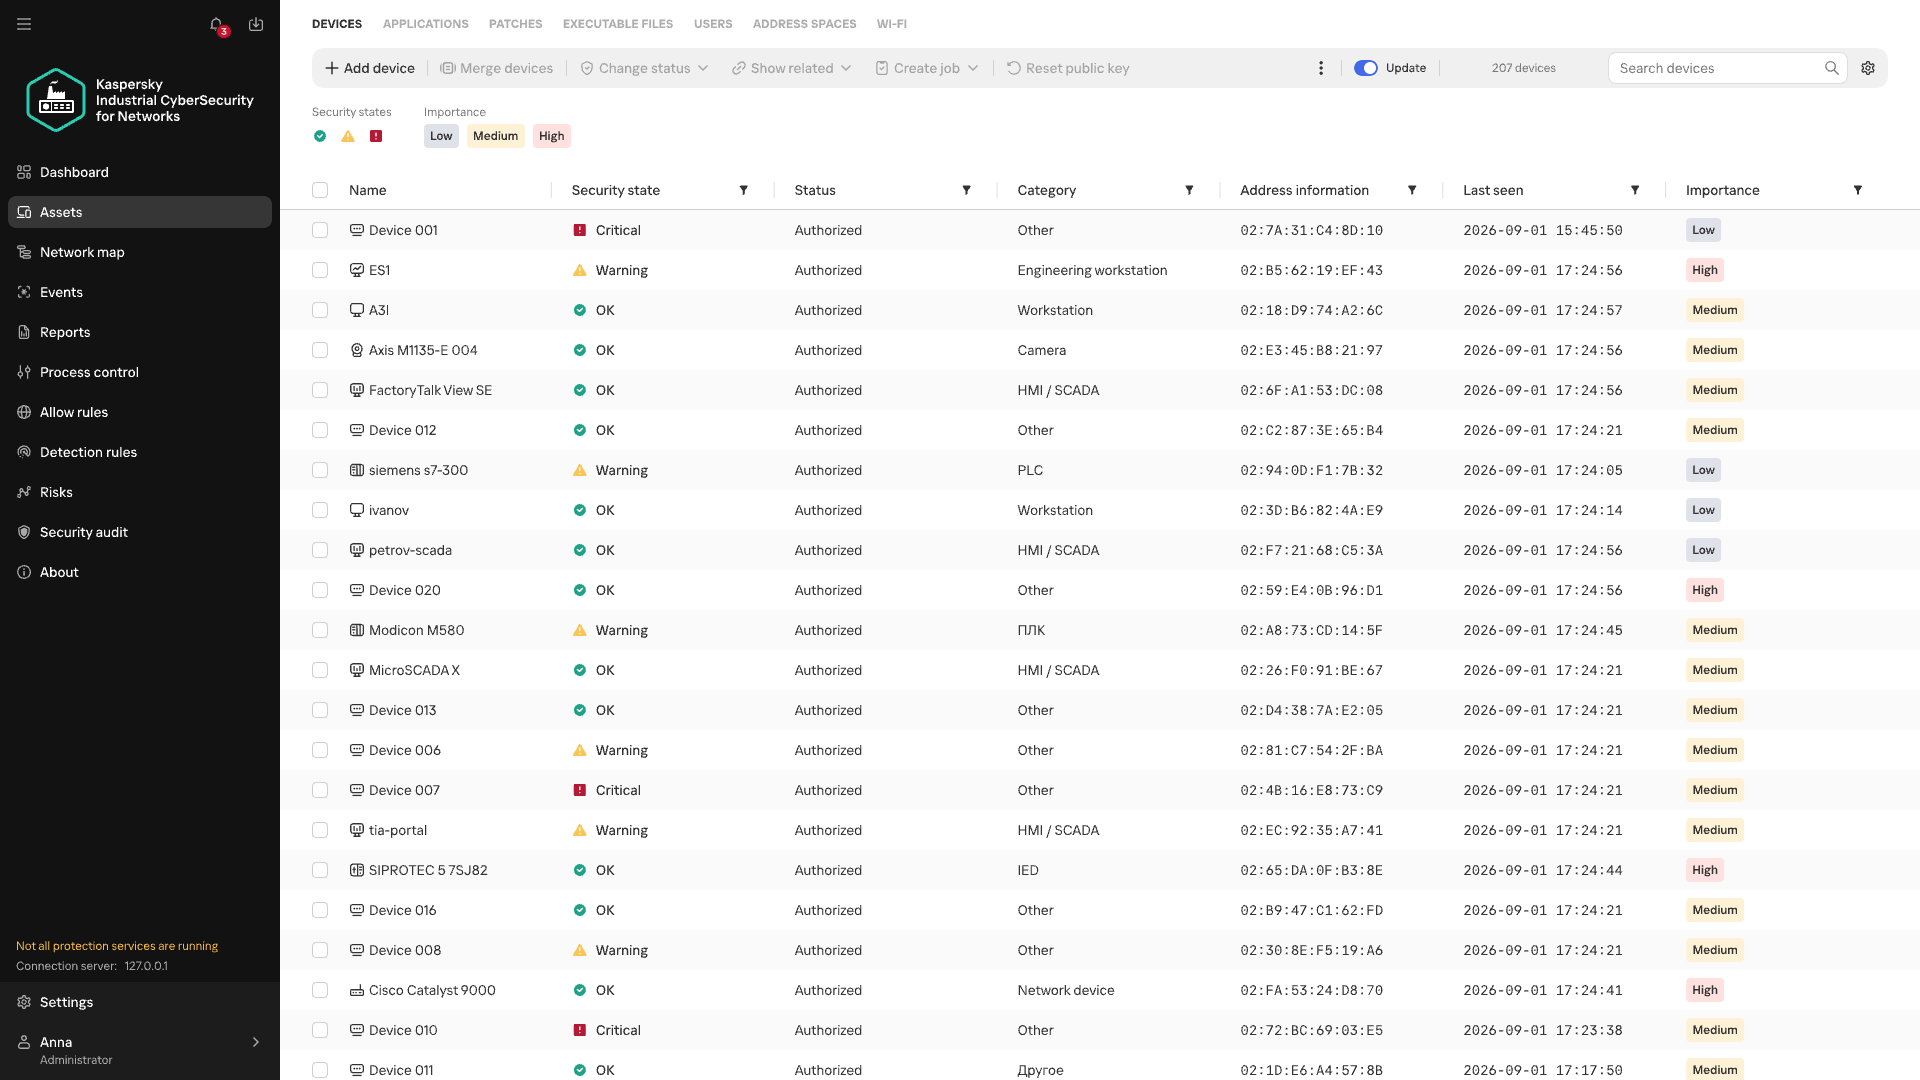
    Devices of unknown category

    Devices of unknown category

    When there isn’t enough direct information about a device, its category can be refined by looking at the patterns of its recurring network interactions. Analyzing these interactions is the job of Machine Learning Event Processor (MLEP), a service included in Kaspersky Industrial CyberSecurity for Networks 5.0. This machine-learning-based event processor can both refine device categories and detect anomalies in their network behavior.

    What data does MLEP analyze?

    To compare device behavior, you don’t need to store every packet as a separate observation (a data object) in the ML model. MLEP represents network sessions as a sequence of short 15-second fragments. For each fragment, MLEP stores information about the endpoints (IP, MAC, and port), the direction of data exchange, the protocol, and the number and size of the packets transmitted. Together these make up an event, which then gets a timestamp. Traffic thus becomes a sequence of events showing which hosts a device communicated with, when, and how communication intensity changed.

    Aggregating data into events also sets the method’s limits. An aggregated fragment can’t be used to reconstruct the exact order of individual packets or the content of commands. MLEP can draw conclusions about a new protocol only if another KICS technology has managed to recognize it. That said, comparing stable network connections and changes in exchange volume doesn’t require a detailed record of every packet. These observations form the basis of the device’s behavioral history.

    From observations to MLEP results

    Each object has its own behavioral history, and one object’s history can’t be applied to another. But the principles of behavior analysis, along with some common rules, work across different objects.

    Let’s look at how this works in MLEP, which is built on a spiking neural semantic network (NSN).

    Event identification

    Neurosemantic networks structure information as a multilayer ordered graph, where the data in each consecutive layer builds on the data in the previous one. The nodes of this graph — that is, the units of information in each layer — act as neurons.The NSN creates dedicated channels to handle different event parameters (port, IP, and so on). Unique parameter values for each channel are stored as neurons in layer 0. The event itself, which consists of a set of parameter values, is stored as a neuron in layer 1 of the network. If an event occurs for the first time, neurogenesis creates a new neuron with input connections to the corresponding parameter neurons. This lets the network learn and operate on the event stream at the same time. If the event has occurred before, the network activates the same neuron that was created when the event first appeared. This way, the network identifies each event precisely. Each neuron that corresponds to an event also collects basic statistics: when it was last activated and how many times it has been activated.
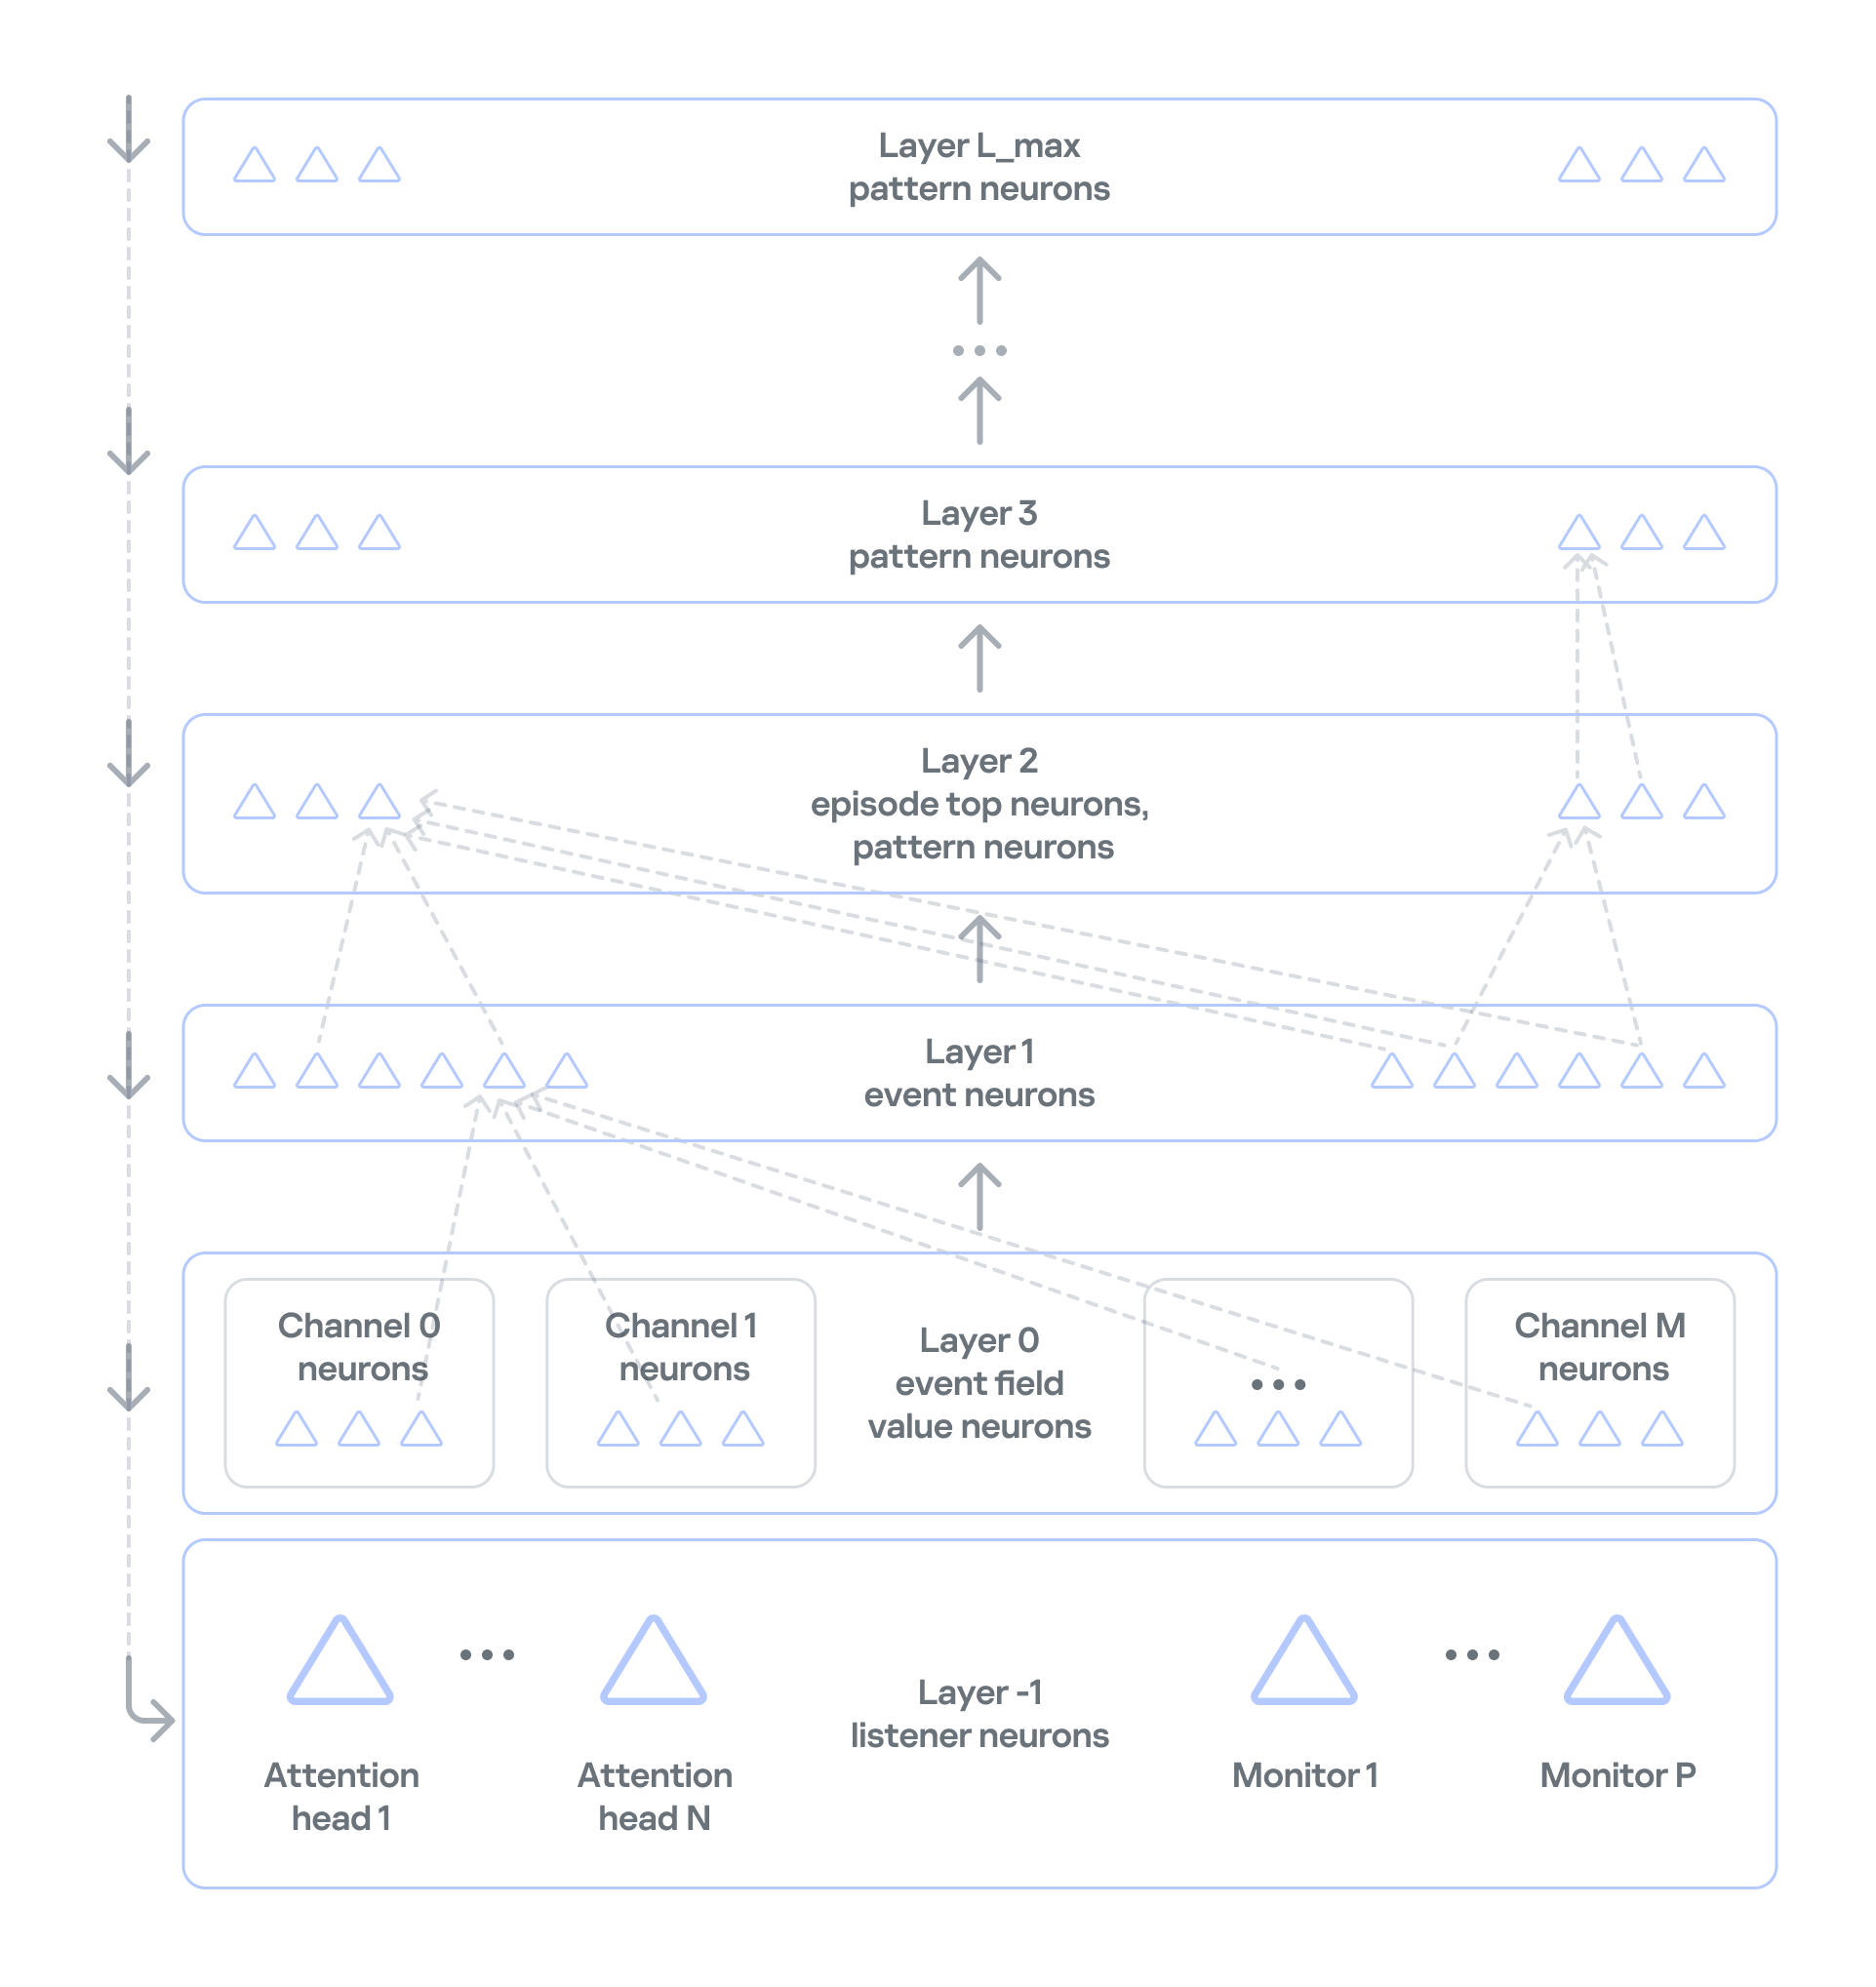
    Event history

    In NSN-based event processing, layer 2 and above store sequences of events over time: recurring patterns and the full history. However, categorization and statistical anomaly detection don’t require storing the full packet sequence or a detailed timeline of every network event. As we noted earlier, events are themselves aggregates, which means the order of network packets has already been averaged out. So MLEP keeps history only temporarily, within each episode (30,000 aggregated events by default), which saves computing resources.

    Statistics processing in MLEP

    MLEP processes statistics mainly through specialized listener neurons on layer −1 (minus one) of the network. Attention heads and monitors are built on these neurons.
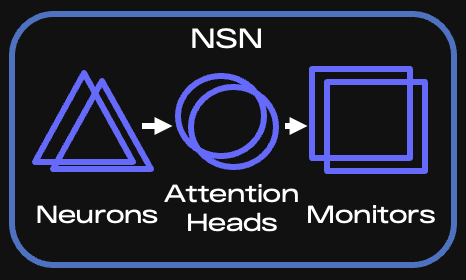
    Key components of the NSN

    Key components of the NSN

    When an event arrives, the corresponding neuron is activated, and the network instantly knows whether that neuron is new or was created earlier. Each attention head subscribes to the events or event features it needs and takes in only the activations of the matching neurons. If an event occurs for the first time, all heads are notified and then decide whether to subscribe (grow a connection to the relevant neuron) and receive information about activations of such neurons from then on.

    It is called a spiking network because activation information is a spike, not a number. This spike tells the head that something it’s interested in has happened.

    An attention head is configured according to scenarios — the situations that MLEP should send alerts about. The core of a head’s configuration is a query, which filters incoming information and serves as the subscription criterion. Unlike regular database queries, this query runs on the stream, so it can react to an event instantly.

    Attention heads work very much like the semantics of ordinary human language. A query has a subject of attention (one or more grammatical subjects) and conditions (the other parts of the sentence). In the infrastructure of an industrial enterprise, the subjects are devices on the network, and the conditions are various aspects of network communication, such as ports, protocol, and average packet size. If a head has many subjects (for example, if it’s interested in every device on an industrial network), it fans out: it creates a child head for each individual value of the subject of attention, that is, each device. The child head then watches a specific device and reports to the parent head.

    Attention heads don’t accumulate or process statistics. They only filter event streams. When an attention head receives a relevant event, it activates and sends a spike to the monitor subscribed to that head.

    Monitors, in turn, have stacks for accumulating and processing events. They can also have their own queries and post-filter information from the head. For example, they can select only new events from those filtered by the head.

    There are several types of monitors:

    • Stat monitors track changes in the average count of specific events (for example, device activity) over time intervals typical for those events, or in the average values of numeric event parameters (for example, changes in device traffic volume).
    • Monitors work from the event alone: they fire when an event has occurred a certain number of times within a given interval, or has occurred for the first time.
    • Similar-behavior monitors work with heads that can generalize events, that is, extract just a few parameters whose combination is shared (generalized) across many events.

    MLEP uses these monitor types to implement scenarios for categorizing devices and detecting their anomalous behavior:

    1. For categorization, MLEP uses attention heads and monitors that identify common behavior across different assets and group devices accordingly. MLEP then takes information from Asset Discovery about the known categories of some assets and extends those categories to other assets in the same group. Because a device can show different types of activity, it may land in several groups. MLEP then makes a weighted assessment across all relevant groups.
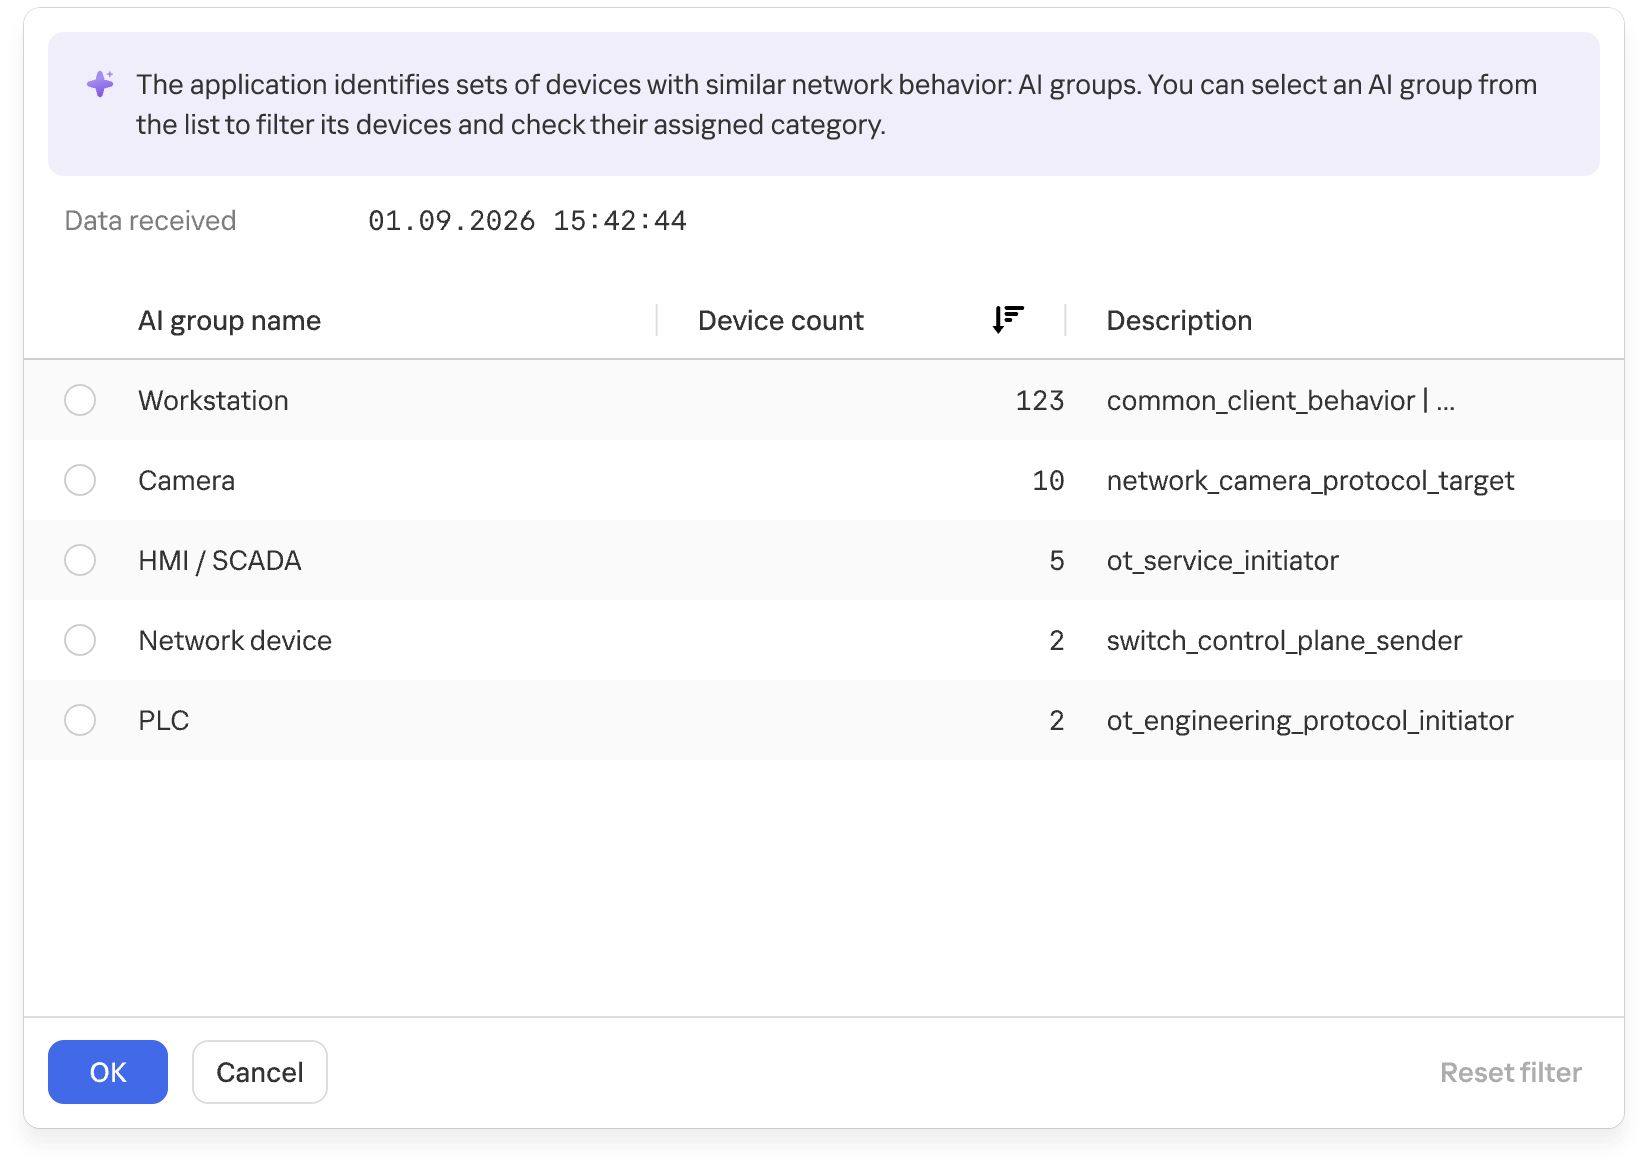
      Groups of devices with similar network behavior

      Groups of devices with similar network behavior

      At the final stage, the system verifies that assigning the category to the asset is permissible. This is again done by special rule monitors loaded into the NSN at system startup. The rules rely on asset metadata available from Asset Discovery and APMs.

    2. MLEP takes a similar approach to anomaly detection: an attention head and a monitor define an anomaly scenario, often loosely. When a monitor activates on such a scenario, MLEP generates an alert about unusual behavior.
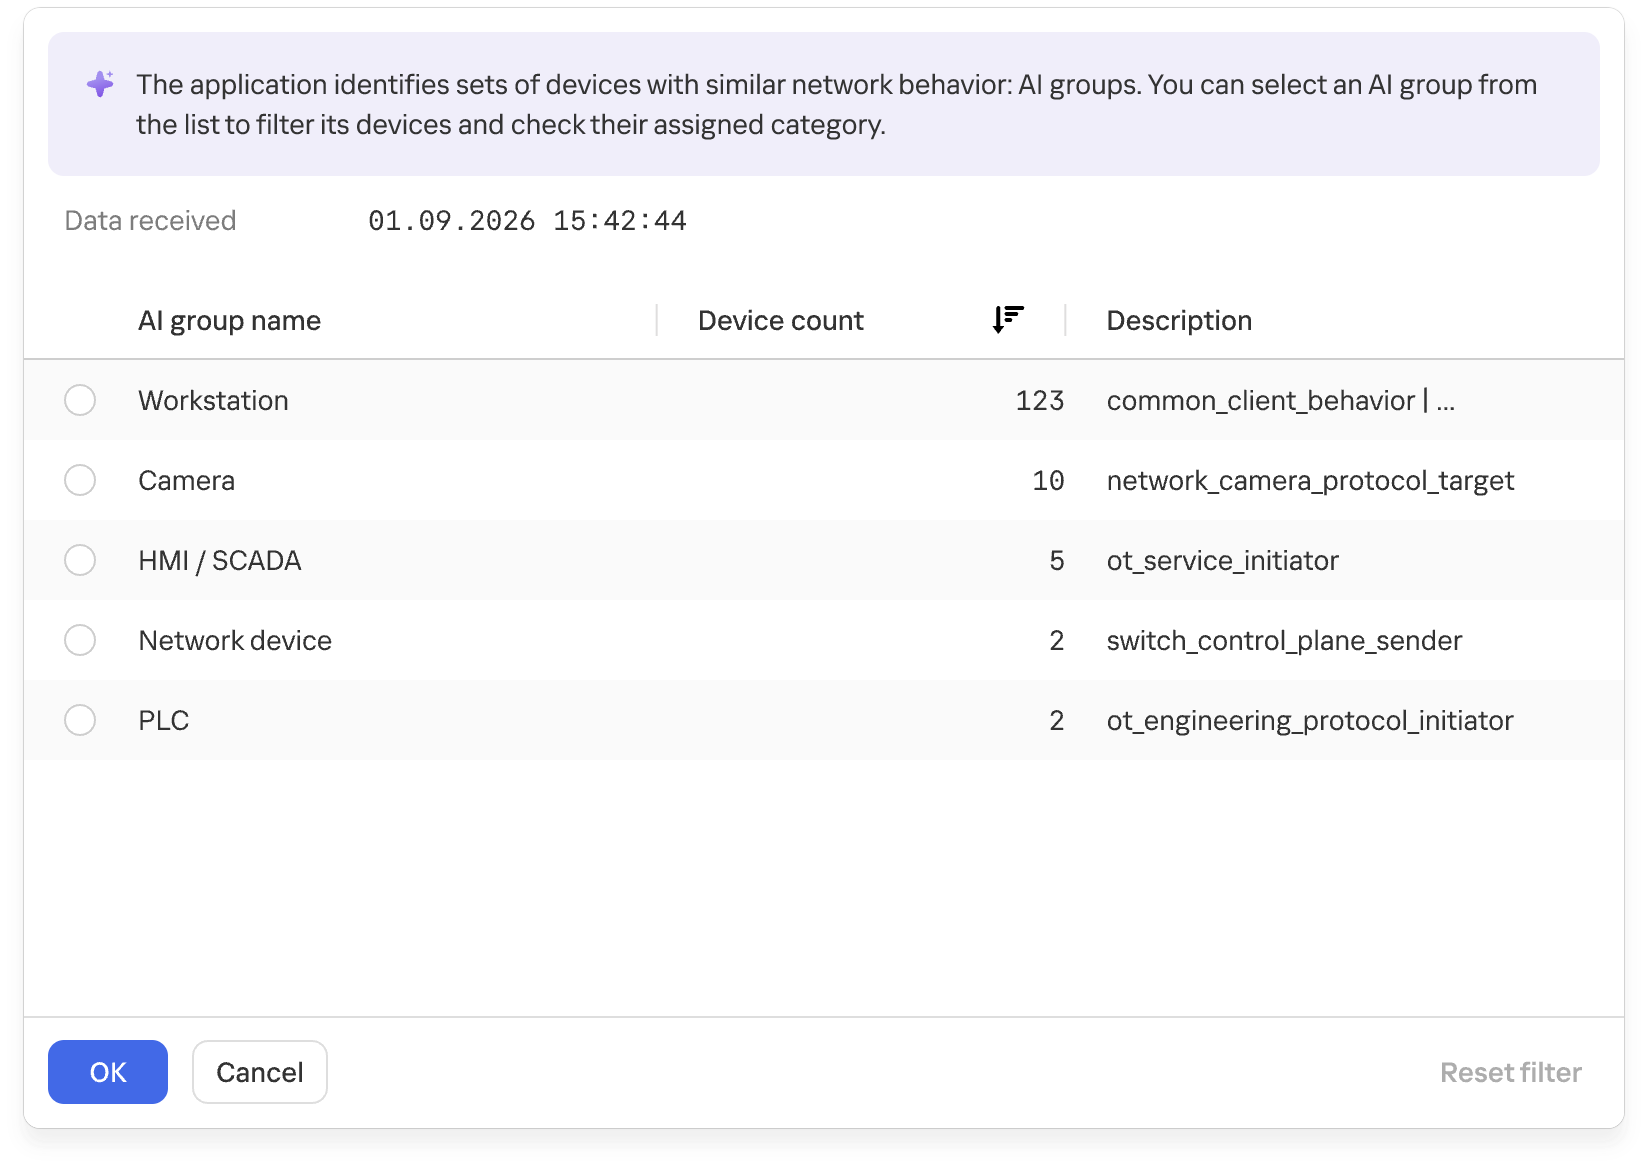
    The current version of MLEP ships with preconfigured heads and monitors.

    The functional dynamic diagram below shows how events from devices on an industrial network are processed.
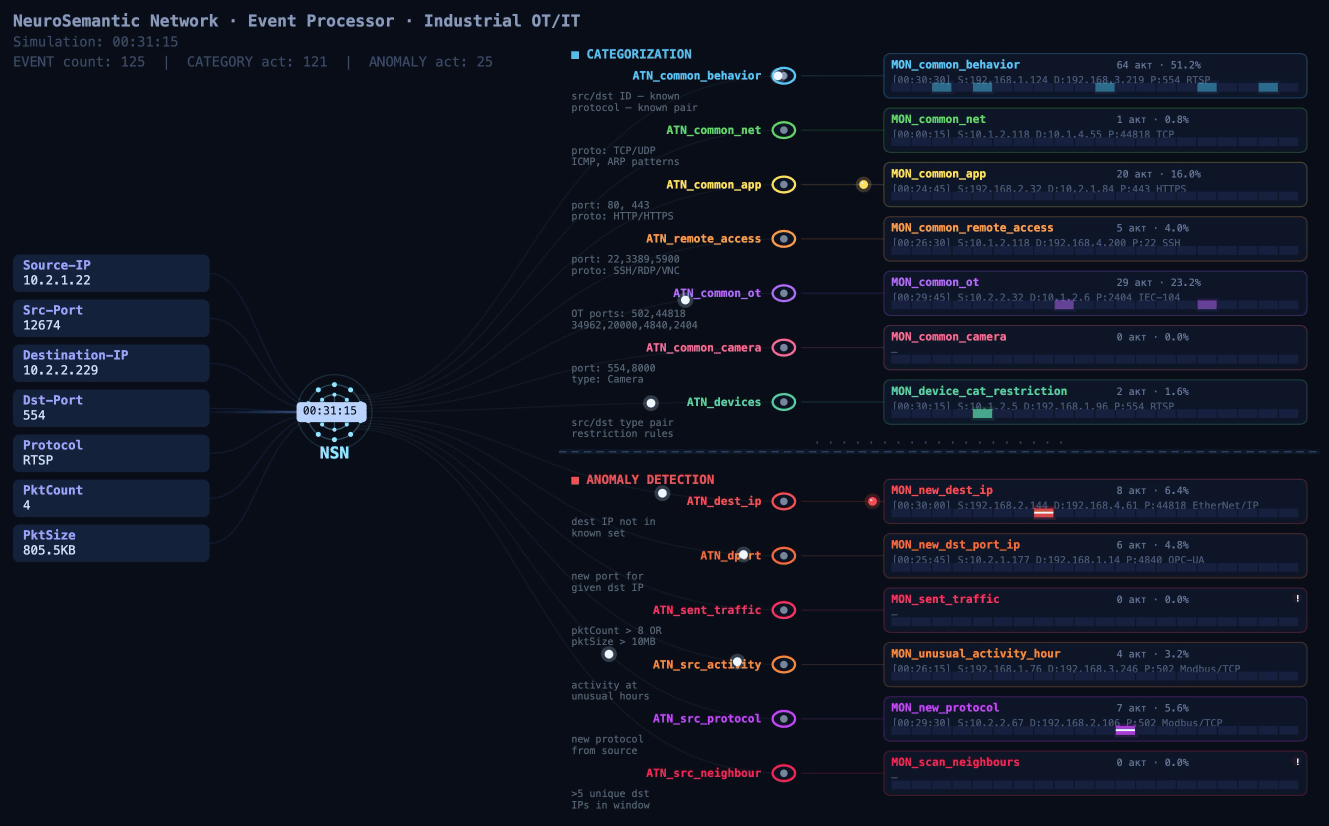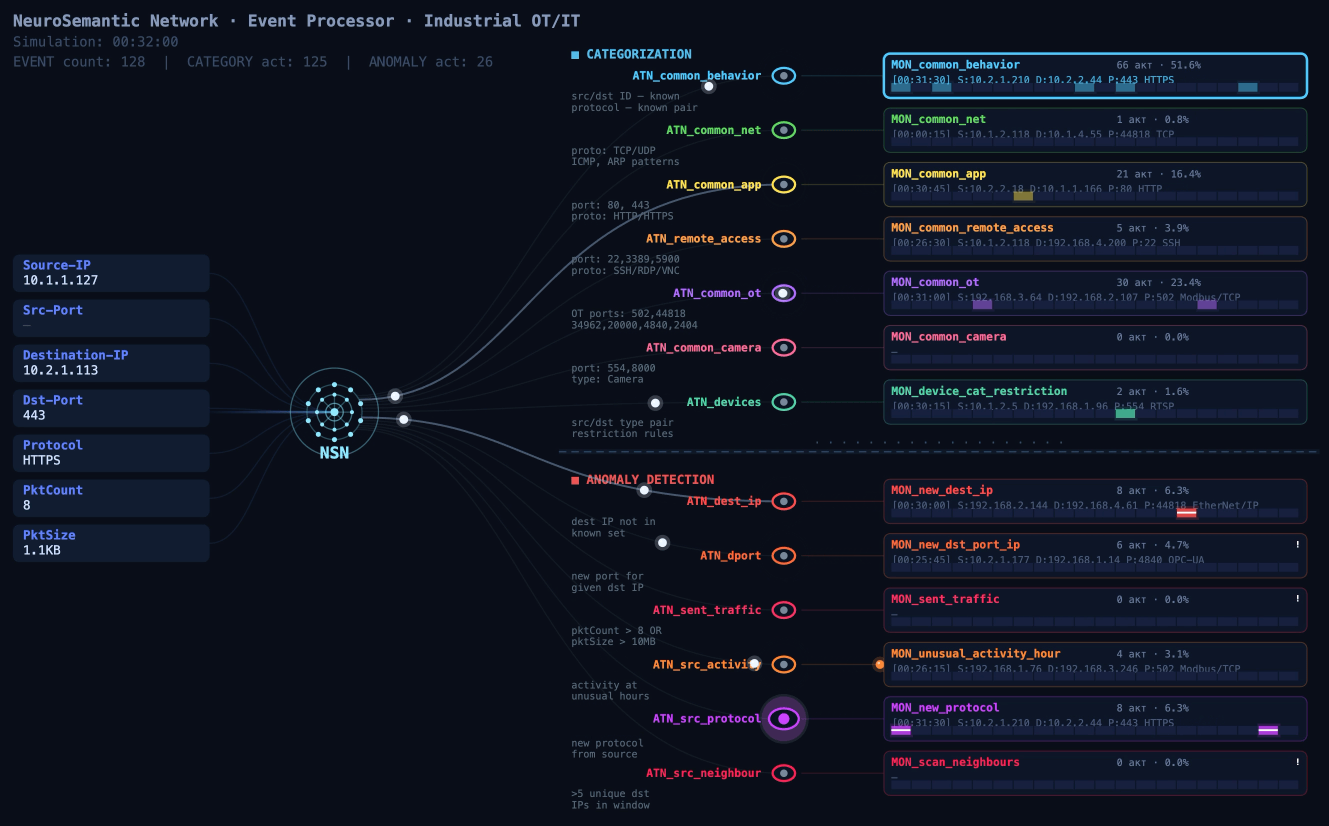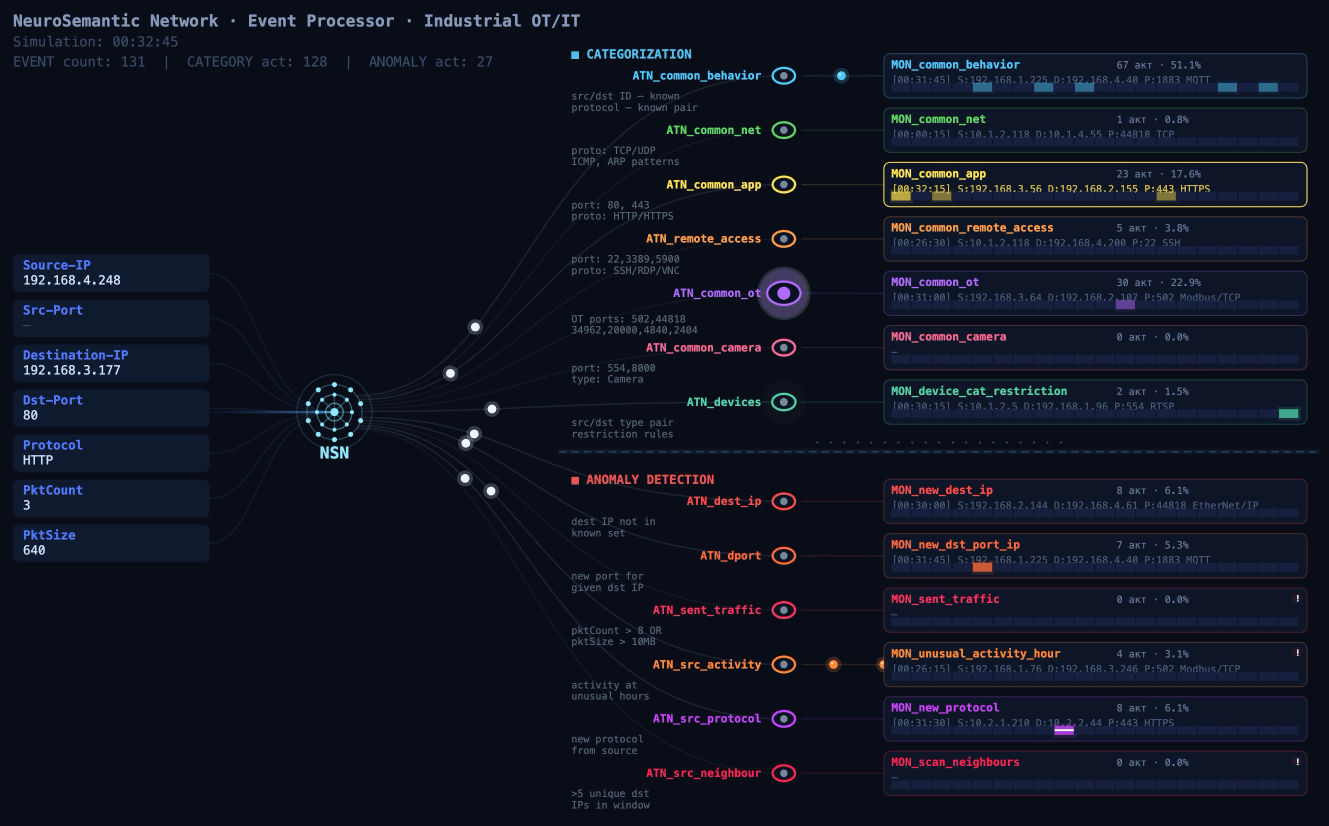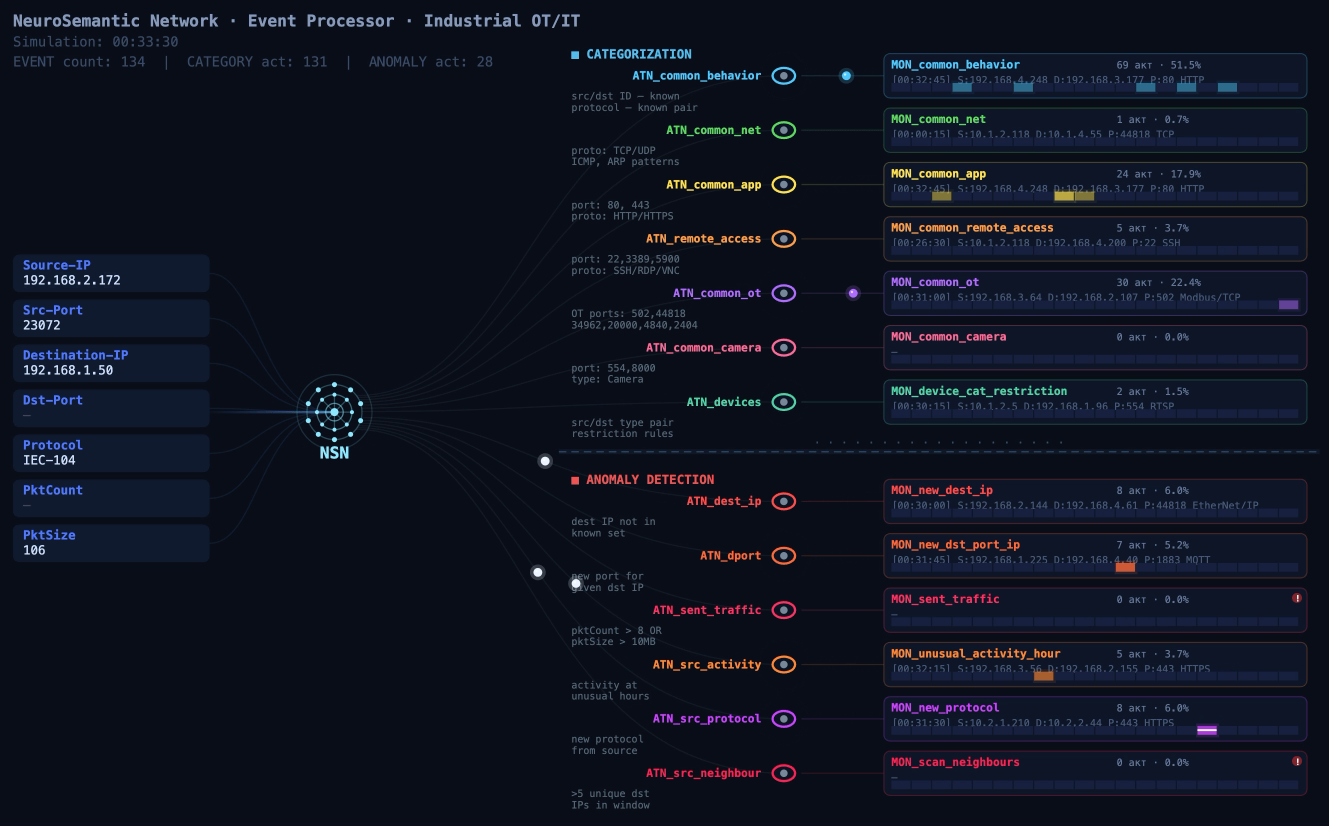
    Event processing flow

    Event processing flow

    MLEP in practice: how behavior helps complete the asset inventory

    At a facility with several similar production lines, device information may be more complete on some lines than on others. On one line, devices are identified as PLCs, while on another, after an upgrade, some hosts show up only as addresses: the available traffic didn’t provide enough information to determine their category. Still, these devices communicate with the same types of HMIs and process data collection servers. Their communication directions, frequency, and volumes may be similar.

    That’s where MLEP comes in. It takes the categories of already known assets and matches recurring features of their network behavior against those of uncategorized devices. When the observed interactions turn out to be similar, MLEP can add a category for that host to the inventory.
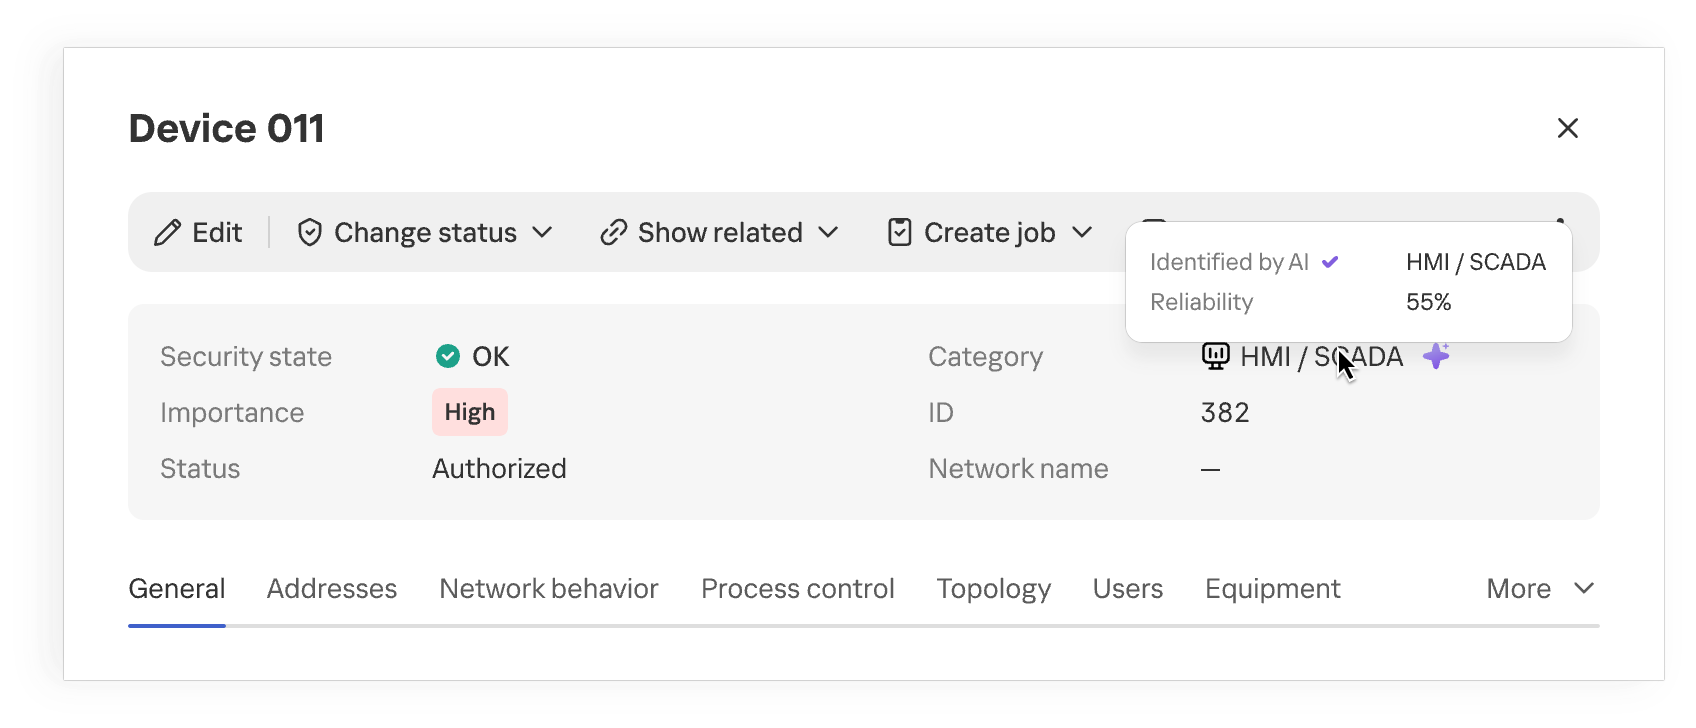
    Device category suggested by MLEP

    Device category suggested by MLEP

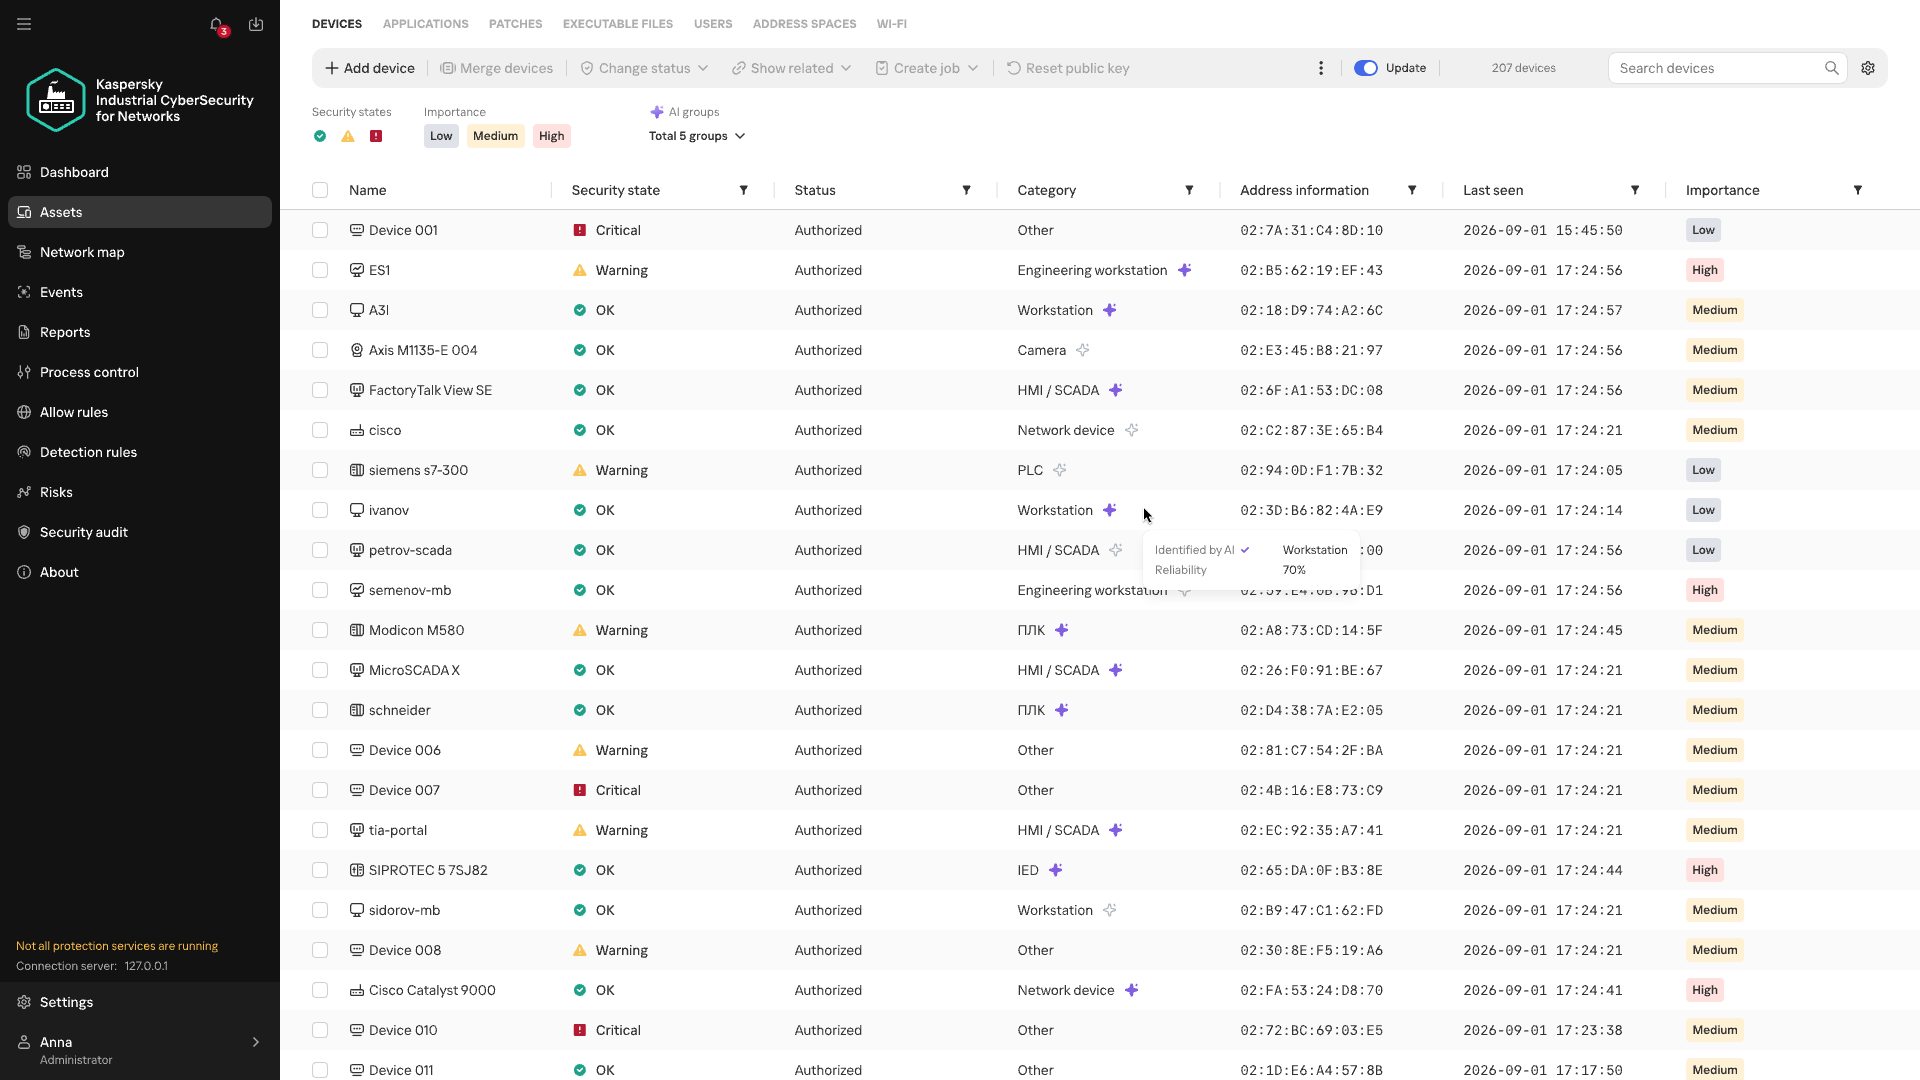
    Once the category is refined, the industrial network map provides more context about the equipment on the network. When analyzing network activity, the analyst immediately sees the device’s suggested category and can skip looking up each IP address in the design diagrams. This approach is especially useful where equipment changes faster than the documentation is updated.

    The suggested category is also checked against existing device information and defined constraints. This helps filter out some contradictory options, but prediction quality still depends on how much of the traffic is visible, especially if the device communicates only rarely.
    Anomalous activity and streaming statistics

    Investigations of real-world attacks show that attackers actively use both standard tools and permitted protocols. You don’t always need to know an attacker’s specific technique in advance to spot potentially malicious activity. Signature-based detection helps find known signs of an attack, but it doesn’t assess how typical an observed interaction is for a particular device. MLEP compares current activity with the device’s usual network profile: which hosts it communicates with, which protocols it uses, when and how much data it transmits, its average packet size, and so on. The changes it detects help guide the direction of the investigation. Correlating these changes with other events and the operational context helps determine whether malicious actions could be behind them. When investigating an incident that has already been detected, anomalies help reconstruct the sequence of actions.

    The first version of MLEP comes with six preconfigured monitors, one for each type of deviation from the device’s usual network profile:

    Anomaly How it helps with event analysis
    New external host Flags a new external connection that wasn’t previously seen in the device’s observed behavior, even if the IP address isn’t listed among known IoCs. Helps check whether this connection appeared at the same time as other suspicious events.
    New combination of destination address and port Shows that the device has begun using a service it hasn’t used before. Once an incident has been detected, this helps trace new connections after the more critical events have been analyzed.
    Unusually large volume of data sent Highlights data transfers that are atypical for the device and helps correlate their timing and direction with other events.
    Atypical activity time Shows that the device was active at a time that’s unusual for it. In an already detected incident, this helps reconstruct the timeline of actions around the main alert.
    New protocol Helps spot a new method of communication, even when the device is communicating with familiar hosts.
    Activity with signs of scanning Shows that the device has started contacting an unusually large number of neighboring hosts. This signal helps reveal possible reconnaissance ahead of attempts to access equipment.

    During an investigation, anomalies help reconstruct the sequence of changes: when a specific host established new connections, switched protocols, increased its data transfer volume, or shifted its operating hours. Matching events by device and time shows an analyst how activity unfolded around an incident that has already been detected.

    This is especially useful when some of the attacker’s actions fell outside the monitored scope or didn’t trigger other KICS technologies. Correlating these changes with the device’s role, protocol analysis data, and events from other technologies gives the analyst a more complete timeline. Behavioral anomalies show exactly where to look for the missing links and which network interactions need attention.
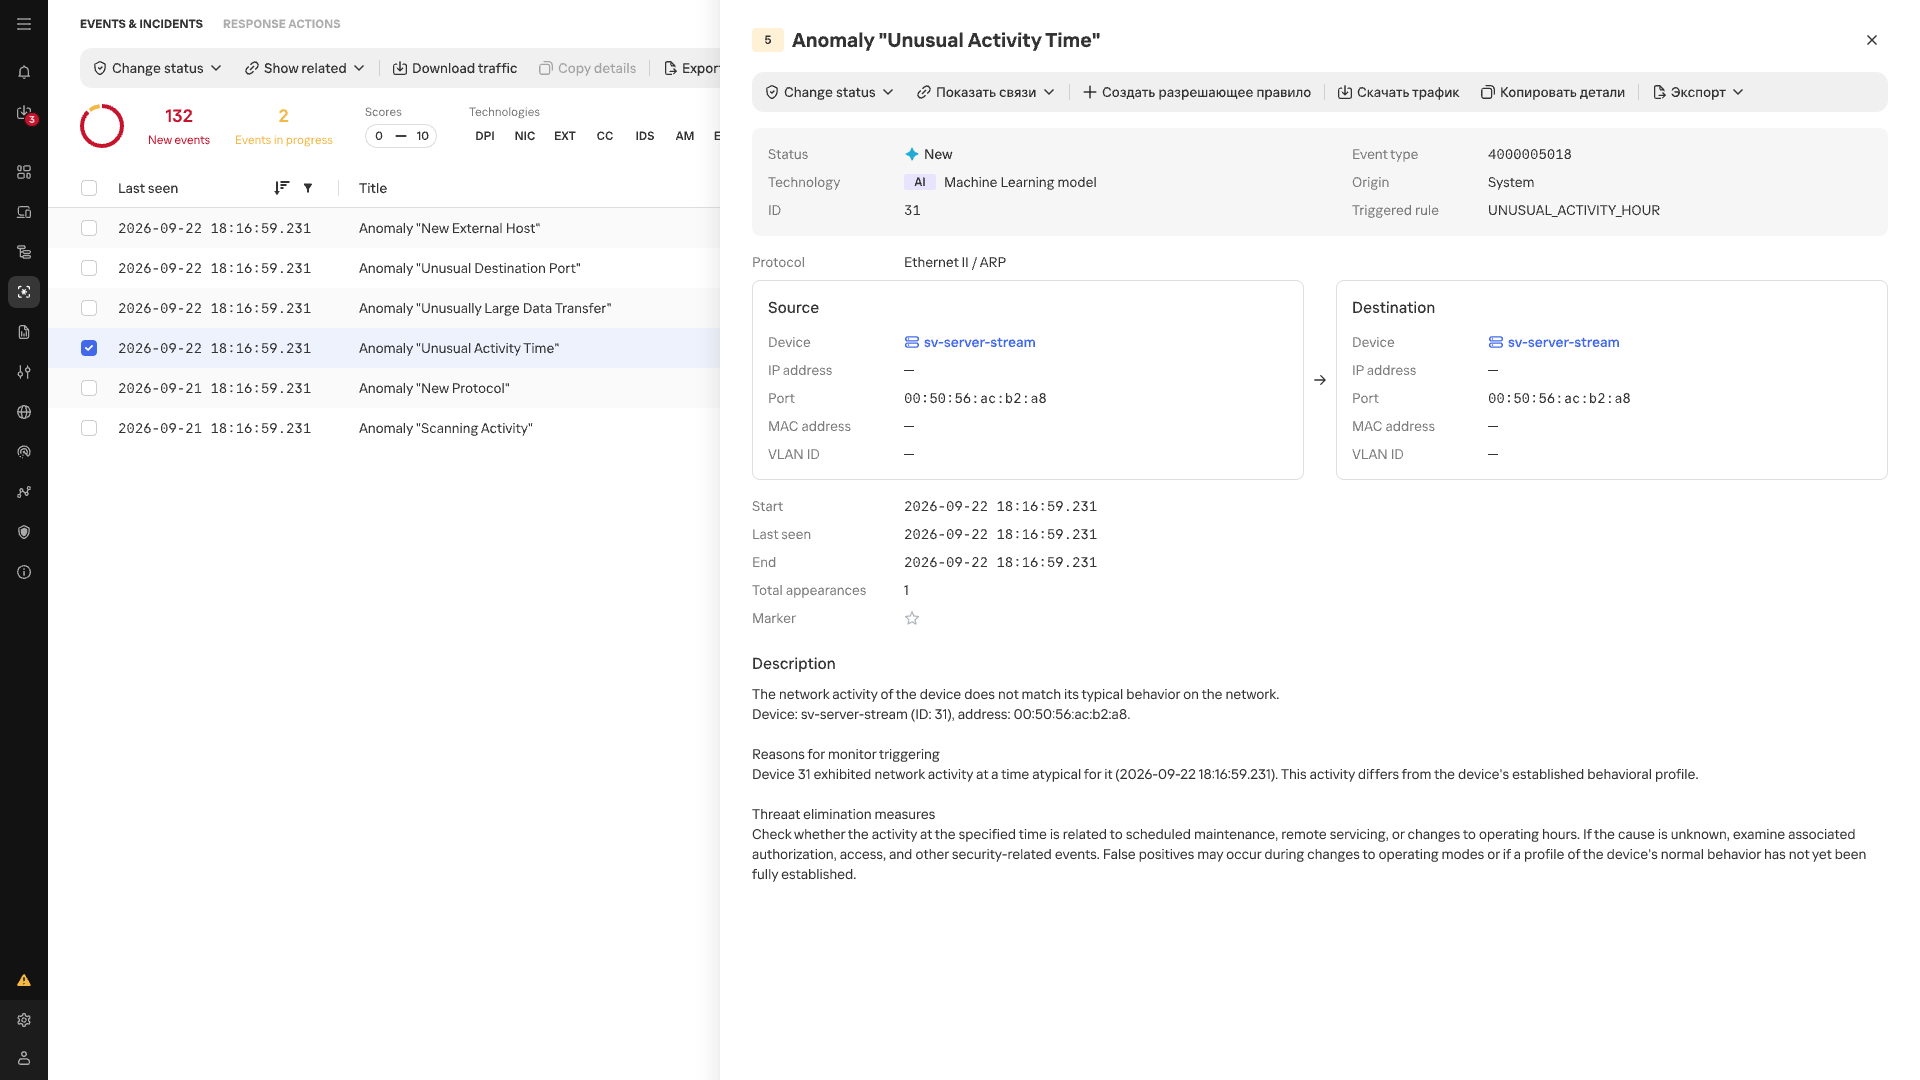
    Atypical Activity Time anomaly card

    Atypical Activity Time anomaly card

    In the event list, anomalies detected by MLEP are marked with an AI label. Each event shows its name, source, destination, timestamp, and the ID of the triggered scenario.

    Conclusion

    In an industrial network, whether behavior is anomalous depends on the host where it occurs and that host’s place in the industrial process. The repetitive nature of many communications makes a change in normal data exchange easier to spot, while knowing a device’s function and criticality helps gauge the possible consequences. Taken together, these observations make network traffic more than a list of connections: it helps assess new events in the context of a specific facility, even without an attack scenario known in advance. Machine learning technologies are well suited to this kind of comprehensive analysis, as they can process and organize huge streams of heterogeneous data. Starting with version 5.0, Kaspersky Industrial CyberSecurity for Networks handles this function with MLEP, which works effectively alongside the product’s existing functionality.

    Source: Securelist (Kaspersky GReAT) · 2026-11-03
  • Filter generation in practice: from algorithms to LLMs

    Filter generation in practice: from algorithms to LLMs

    A modern organization protects its information systems with a whole suite of technologies that generate thousands of security alerts every day. Looking at these alerts in bulk, you’ll see that a significant share are false positives. Ideally, these alerts would be filtered out automatically so that analysts could focus on the ones that may point to a real incident. However, writing filters is a time-consuming task in itself. To create a correct filter, an analyst needs to:

    • Review the logs
    • Identify the source of the activity
    • Define filtering boundaries
    • Choose filtering criteria
    • Write a rule
    • Check that the filter is robust

    This post looks at how filter creation itself can be automated to reduce analyst workload.

    Filter validity criteria

    In the context of security alerts, a filter is a combination of event field values that marks a detection as a false positive and not worth the analyst’s attention. Filters can be generated for any combination of event fields, but not every combination yields a valid filter. That’s why we need to define validity criteria: conditions showing that a specific filter actually removes noise and doesn’t suppress useful alerts.

    Detection rules in security systems typically contain a set of conditions, and each of them can generate an alert. A specific event triggers a given fragment of a detection rule. The set of events that a given fragment responds to is what we’ll call its context. A good filter should cover the entire context where possible, without going beyond it. Filters that are too broad or too narrow are useless. For example, a filter based solely on PowerShell would exclude too many events, including some that deserve the analyst’s attention. Most of the filtered events would also be unrelated to the rule in question. A filter on a specific ID, on the other hand, would cover only one event, which may never recur.

    Problems in filter generation

    We can run into a number of problems when creating filters. First, events often contain an excessive number of fields (around 400 on average), and most of them aren’t needed for filtering. At the same time, generating and ranking combinations of these fields is also fairly resource-intensive. So, the first step is to discard the irrelevant fields and keep only those worth using in the filter. For example, out of 400 fields in an event, four may be enough for filtering.

    Another problem is string normalization. Field values (for example, the path to the same application on different systems) can vary depending on system settings, user folder names, and so on. For a filter to account for all these variations, the strings must be normalized. For file paths, in particular, you can replace the drive letter and user folders with standard environment variables and convert all paths to a single case.

    Finally, if a filter completely mirrors the query of a detection rule, it effectively disables that rule. To fix this, remove the event fields used in the detection rule from the filter. For example, if a rule triggers on a file path, there are two ways to filter out unwanted alerts:

    • In the filter, use fields other than the file path.
    • Use a part of the file path that the rule doesn’t use. For example, for the rule file_path: ".../something.exe", you can set up a filter that excludes events with the user/unique_files/ directory in the file path.

    Filtering security alerts with an algorithm

    Given the problems described above, automatically generating filters for security alerts should consist of the following steps:

    1. An analyst receives a security alert that they assess as a false positive and uses the filter generator.
    2. The generator takes the 400-field event from the alert, along with the rule that triggered on it, and determines the context.
    3. The generator selects the fields that are relevant to the filter.
    4. The generator normalizes the strings.
    5. The generator builds different combinations of the selected fields. To do this, we applied the FP-Growth (frequent pattern growth) algorithm to the context determined earlier. FP Growth builds a tree of frequently occurring items (fields) from a dataset (in our case, the context) and discards items that aren’t frequent enough. This reduces the number of combinations to check, which lowers the cost of finding the most relevant ones.
    6. The generator ranks the resulting combinations and offers the analyst the top three to choose from.

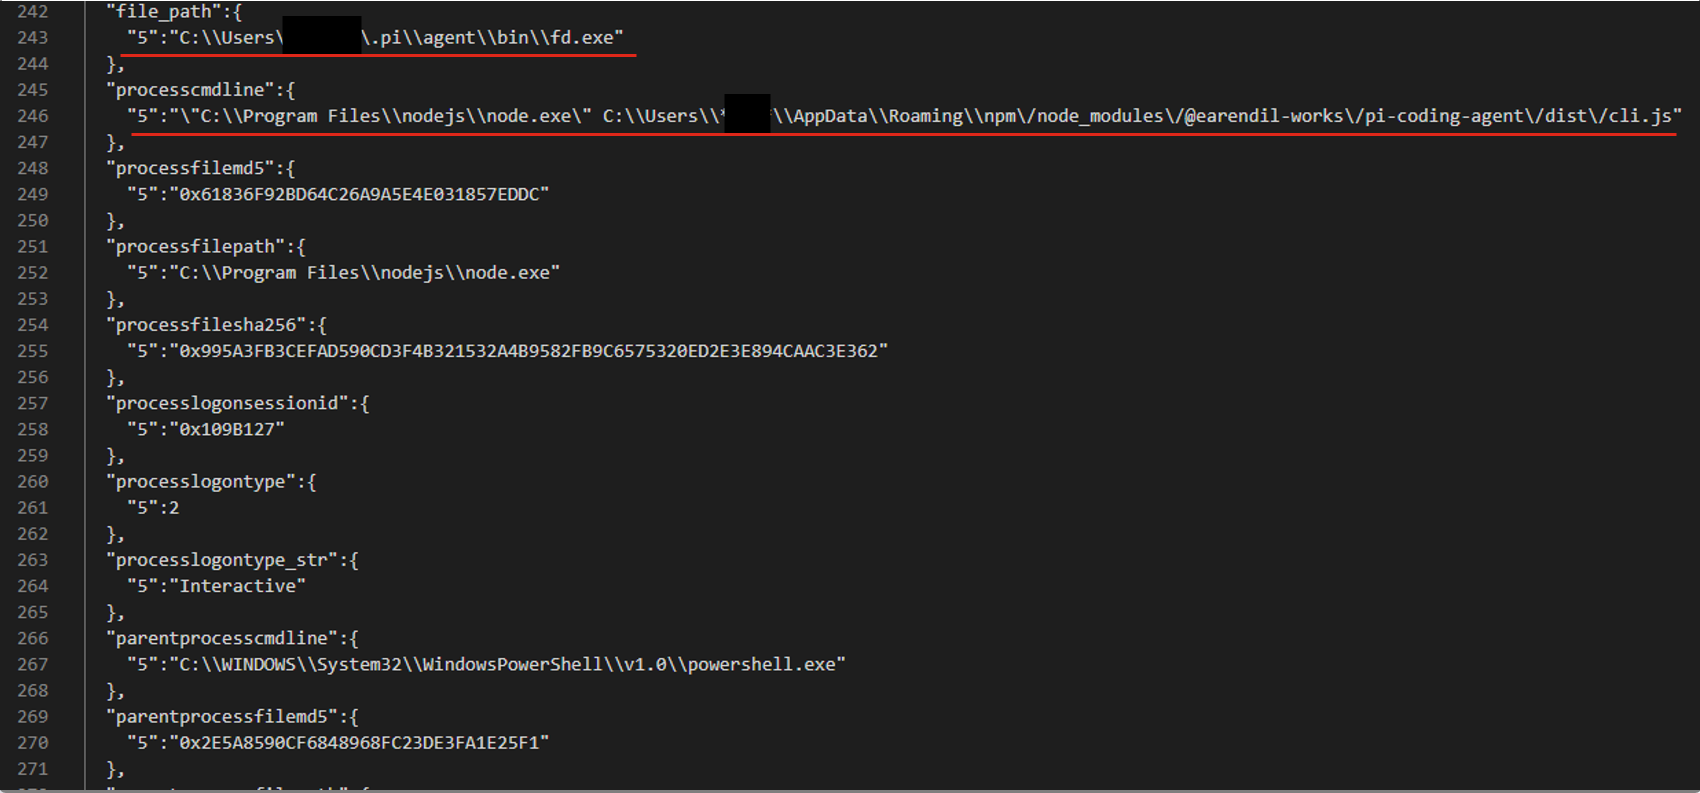
    For example, consider an event described by the following JSON:

    After generating and ranking the combinations, we got three filters based on file paths:

    • processcmdline:("nodejs\\node.exe" AND "*****\\appdata\\roaming\\npm\/node_modules\/pi-coding-agent\/dist\/cli.js")
    • file_path:"*****/.pi\\agent\\bin\\fd.exe"
    • processcmdline: "programfiles\\nodejs\\node.exe"

    The last filter turned out to be too broad, but the analyst marked the other two as valid.

    Pros and cons of the algorithmic approach

    The algorithmic approach to filter generation has several advantages. First, it’s simple and deterministic: the same alert always produces the same result. Second, it’s interpretable, meaning we can see why a given combination ranked near the top of the list and why a particular field didn’t make it into the list of candidate fields at all. Third, the stages of the process are independent of each other, so individual steps can be improved and tuned without the risk of breaking the algorithm elsewhere. Finally, it has no external dependencies or models, which makes it easy to deploy in any customer environment.

    However, it also has drawbacks. The first is its dependence on context. If there’s no context for some reason — for example, the rule’s first-ever trigger — a filter can’t be created. The second problem is string normalization. There’s a high chance of running into atypical cases that the normalization rules don’t cover. Often such cases can’t be described correctly at all, because they contradict each other.

    These problems can be solved with large language models (LLMs). When an LLM generates the filters, no context is needed, because the LLM doesn’t iterate over or rank combinations. The LLM also takes a more flexible approach to string normalization, including non-standard cases. That said, an LLM doesn’t have to be involved at every stage of the generation process. We decided to keep the algorithmic solution where it works well. For example, a simple algorithm selects suitable fields without errors, so we didn’t move this stage to the model.

    Filter generation with an LLM

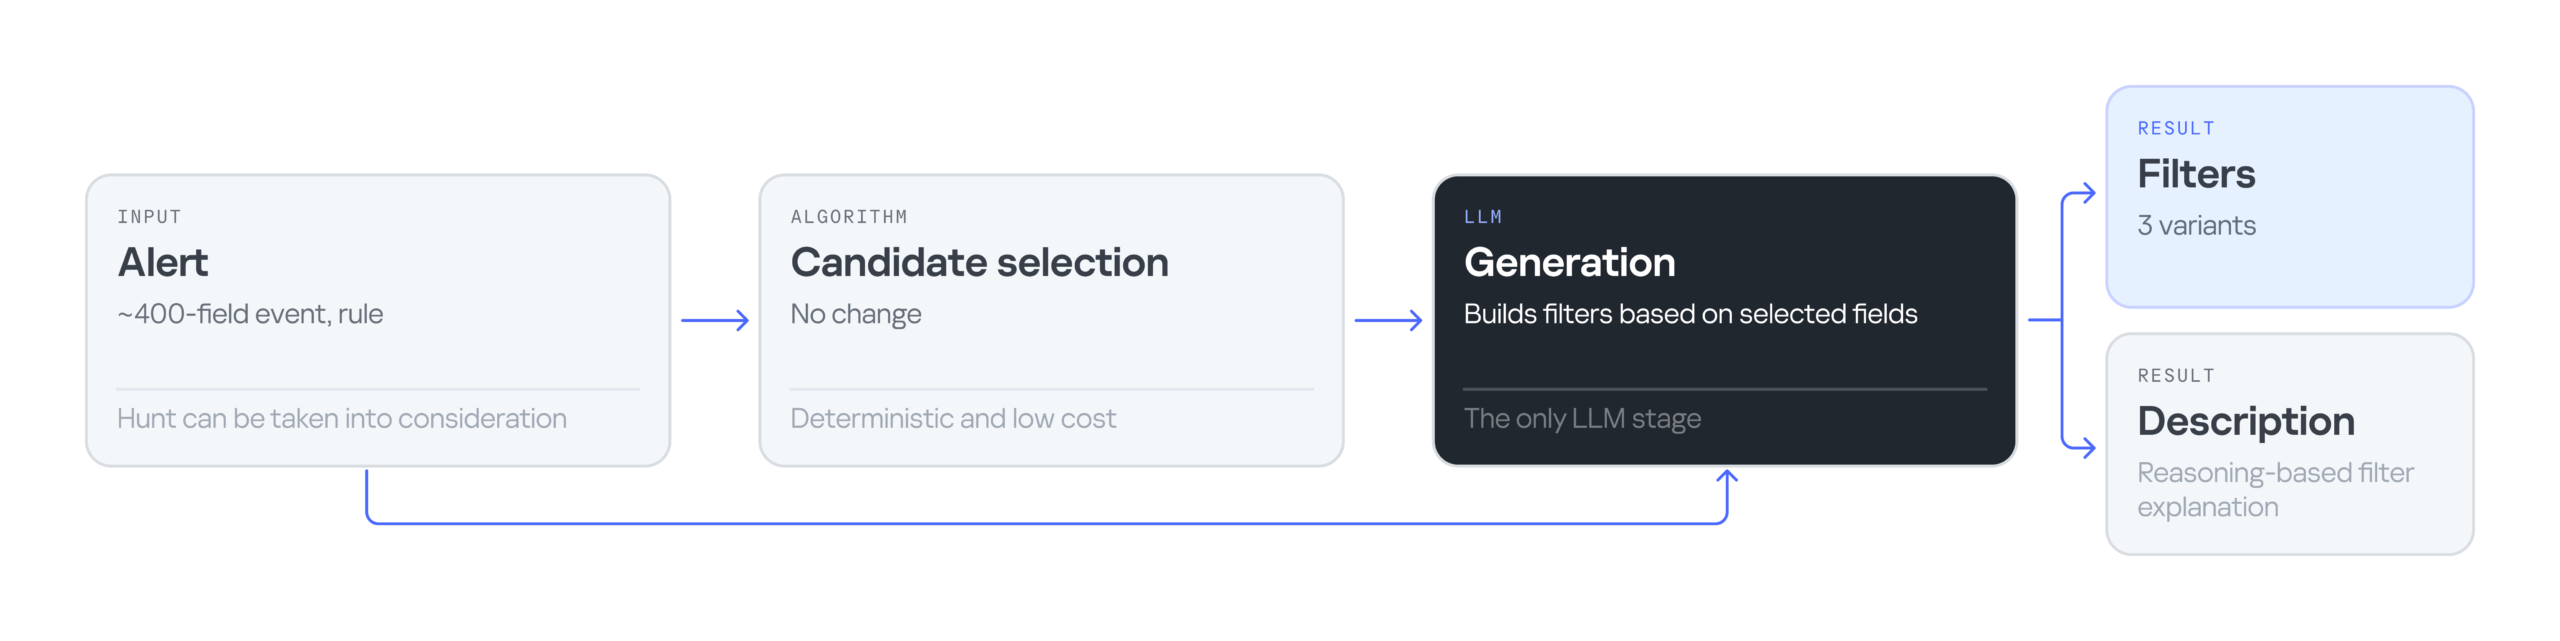
    The LLM-based filter generation looks like this:

    The input is still an alert containing an event with 400 fields, plus the rule that triggered on that event. Then an algorithm selects the most suitable fields for the filter. Next, the LLM processes the input — the event, the selected fields, and the detection rule — and generates three filter options along with an explanation for them. The explanation helps the analyst understand why these particular filters were suggested and make an informed choice.

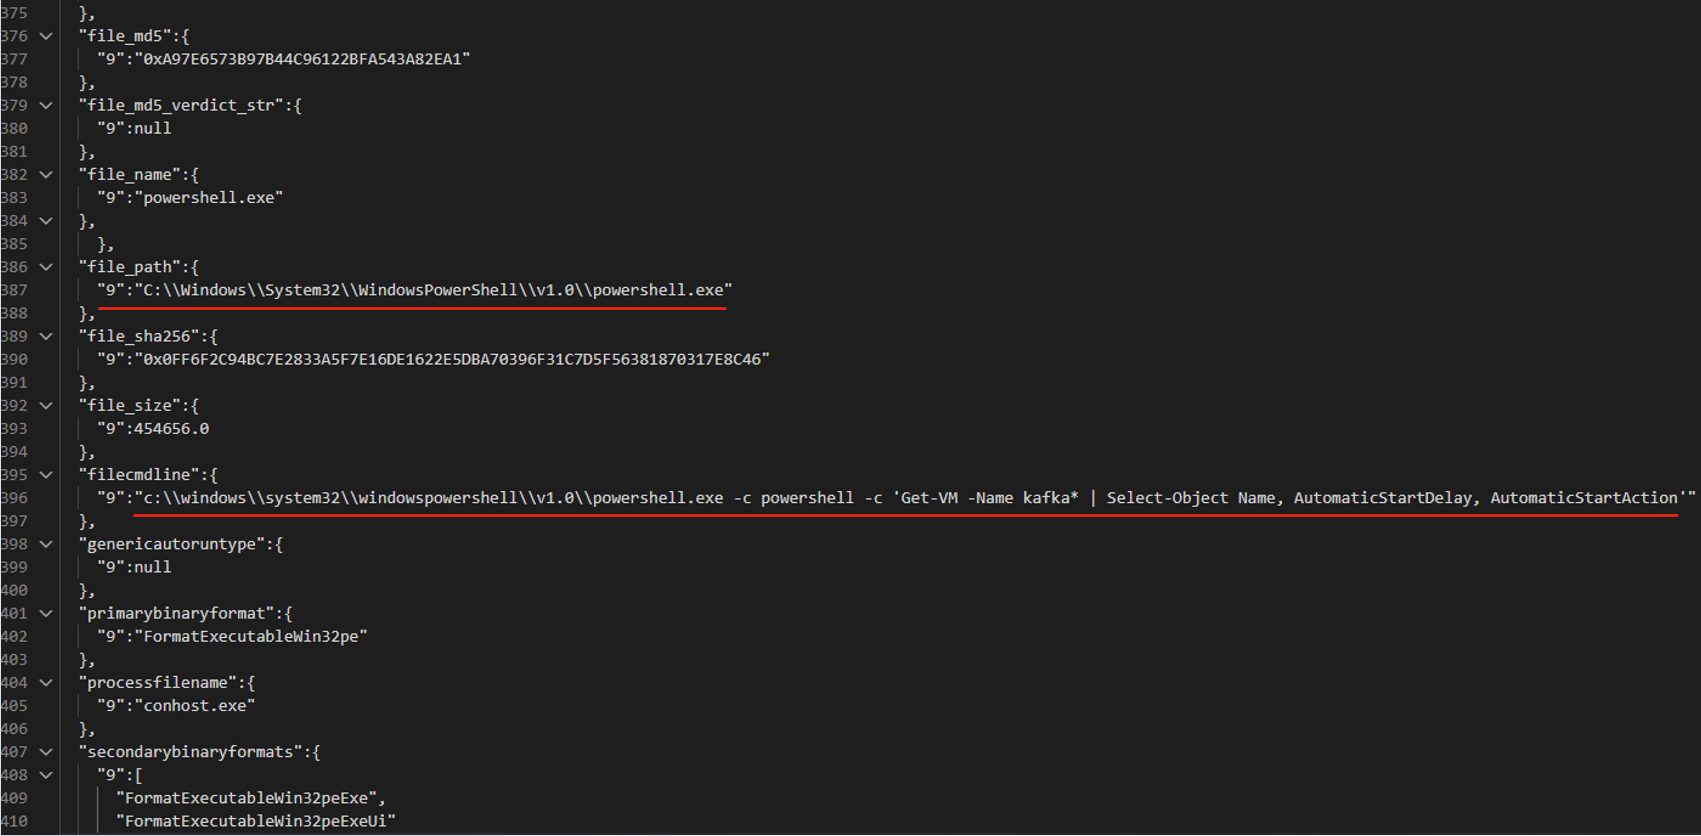
    Consider the following event in JSON format:

    The LLM suggested three filter options that all contain the same command line fragment:

    • file_path: "\\WindowsPowerShell\\powershell.exe" AND filecmdline: "Get-VM -Name kafka\*"
    • filecmdline: "Get-VM -Name kafka\*"
    • filecmdline: "kafka*"

    As in the previous example, two of the three output filters were valid. The last one was too broad to be usable. The analyst chose the first filter with minor edits:

    file_path: "powershell.exe" AND filecmdline: "Get-VM -Name kafka\*"

    Pros and cons of generating filters with an LLM

    Using an LLM solved the problems of purely algorithmic filter generation: dependence on context and errors in string normalization. However, the single-request approach had its own drawbacks. First, it had no output validation. The LLM returned filters as-is, with no syntax check and no way to correct errors. Second, unlike in the algorithmic version, all filter generation tasks were handled by a single system prompt. As a result, a minor fix in one place could break the logic in another.

    Using multiple AI agents

    To address the problems of generating filters with a single model and a single system prompt, we tried distributing the tasks across different LLM agents. In this version, we brought in agents as early as the stage of selecting relevant fields. The chain includes four agents in total:

    • Selector: selects the relevant fields.
    • Generator: generates filters.
    • Validator: evaluates the generated filters. If the filters are found to be invalid, it returns the task to the generator. If the selected fields are found to be irrelevant, it starts a new field selection cycle. If the filters pass validation, or the limit on regeneration attempts is reached, the valid filters (or the best ones available) are passed to the analyst.
    • Commentator: analyzes the output filters and explains which field values were used and why.

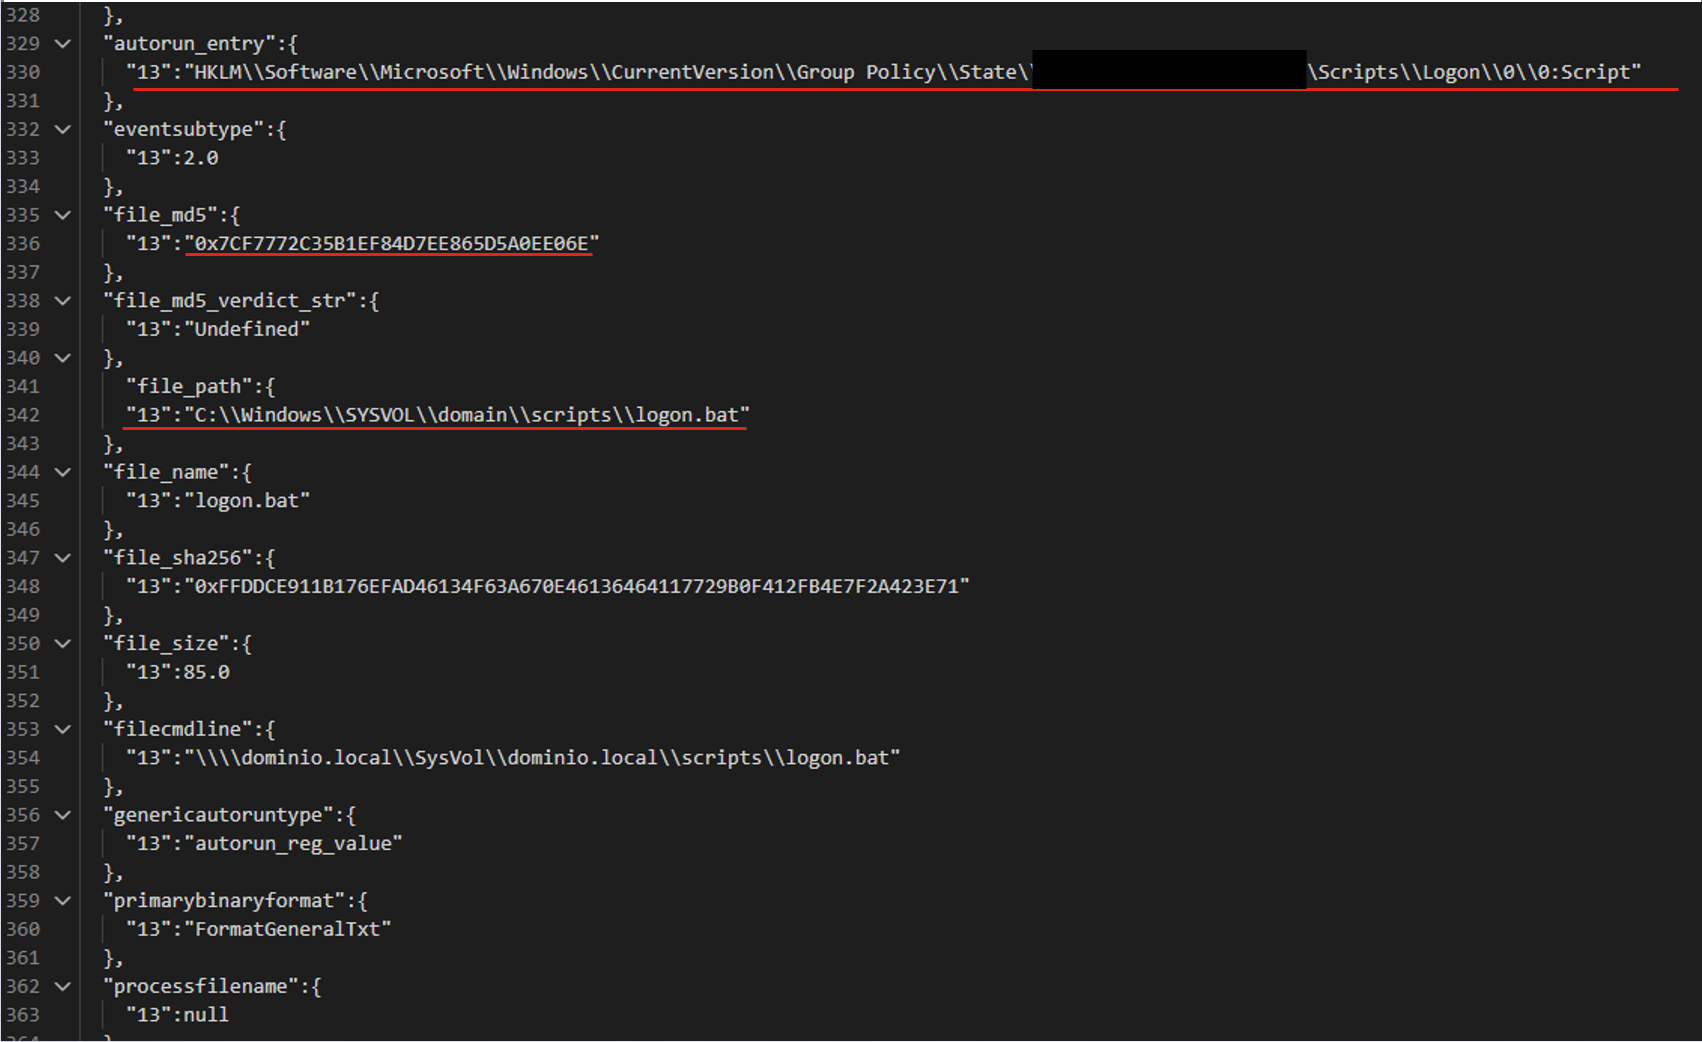
    For the following JSON event, the agents produce three valid filters based on the file path.

    The filters differ in the additional parameters that support the detection:

    • file_path:"sysvol\\domain\\scripts\\logon.bat"
    • file_path:"sysvol\\domain\\scripts\\logon.bat" AND file_md5:"0x7..6E"
    • autorun_entry: "Group Policy\\State" AND file_path: "SYSVOL\\domain\\scripts\\logon.bat"

    Pros and cons of the agent-based approach

    LLM agents give us a system that can validate and correct filters. Its modular architecture also lets us tune and improve different stages of generation independently. However, this approach makes more LLM calls than the previous ones, so the system is slower. It also depends on access to a model, which may not be available in the organization’s isolated environment.

    Evaluating the filter generation system

    To evaluate how well the filter generation system works, we use two main metrics:

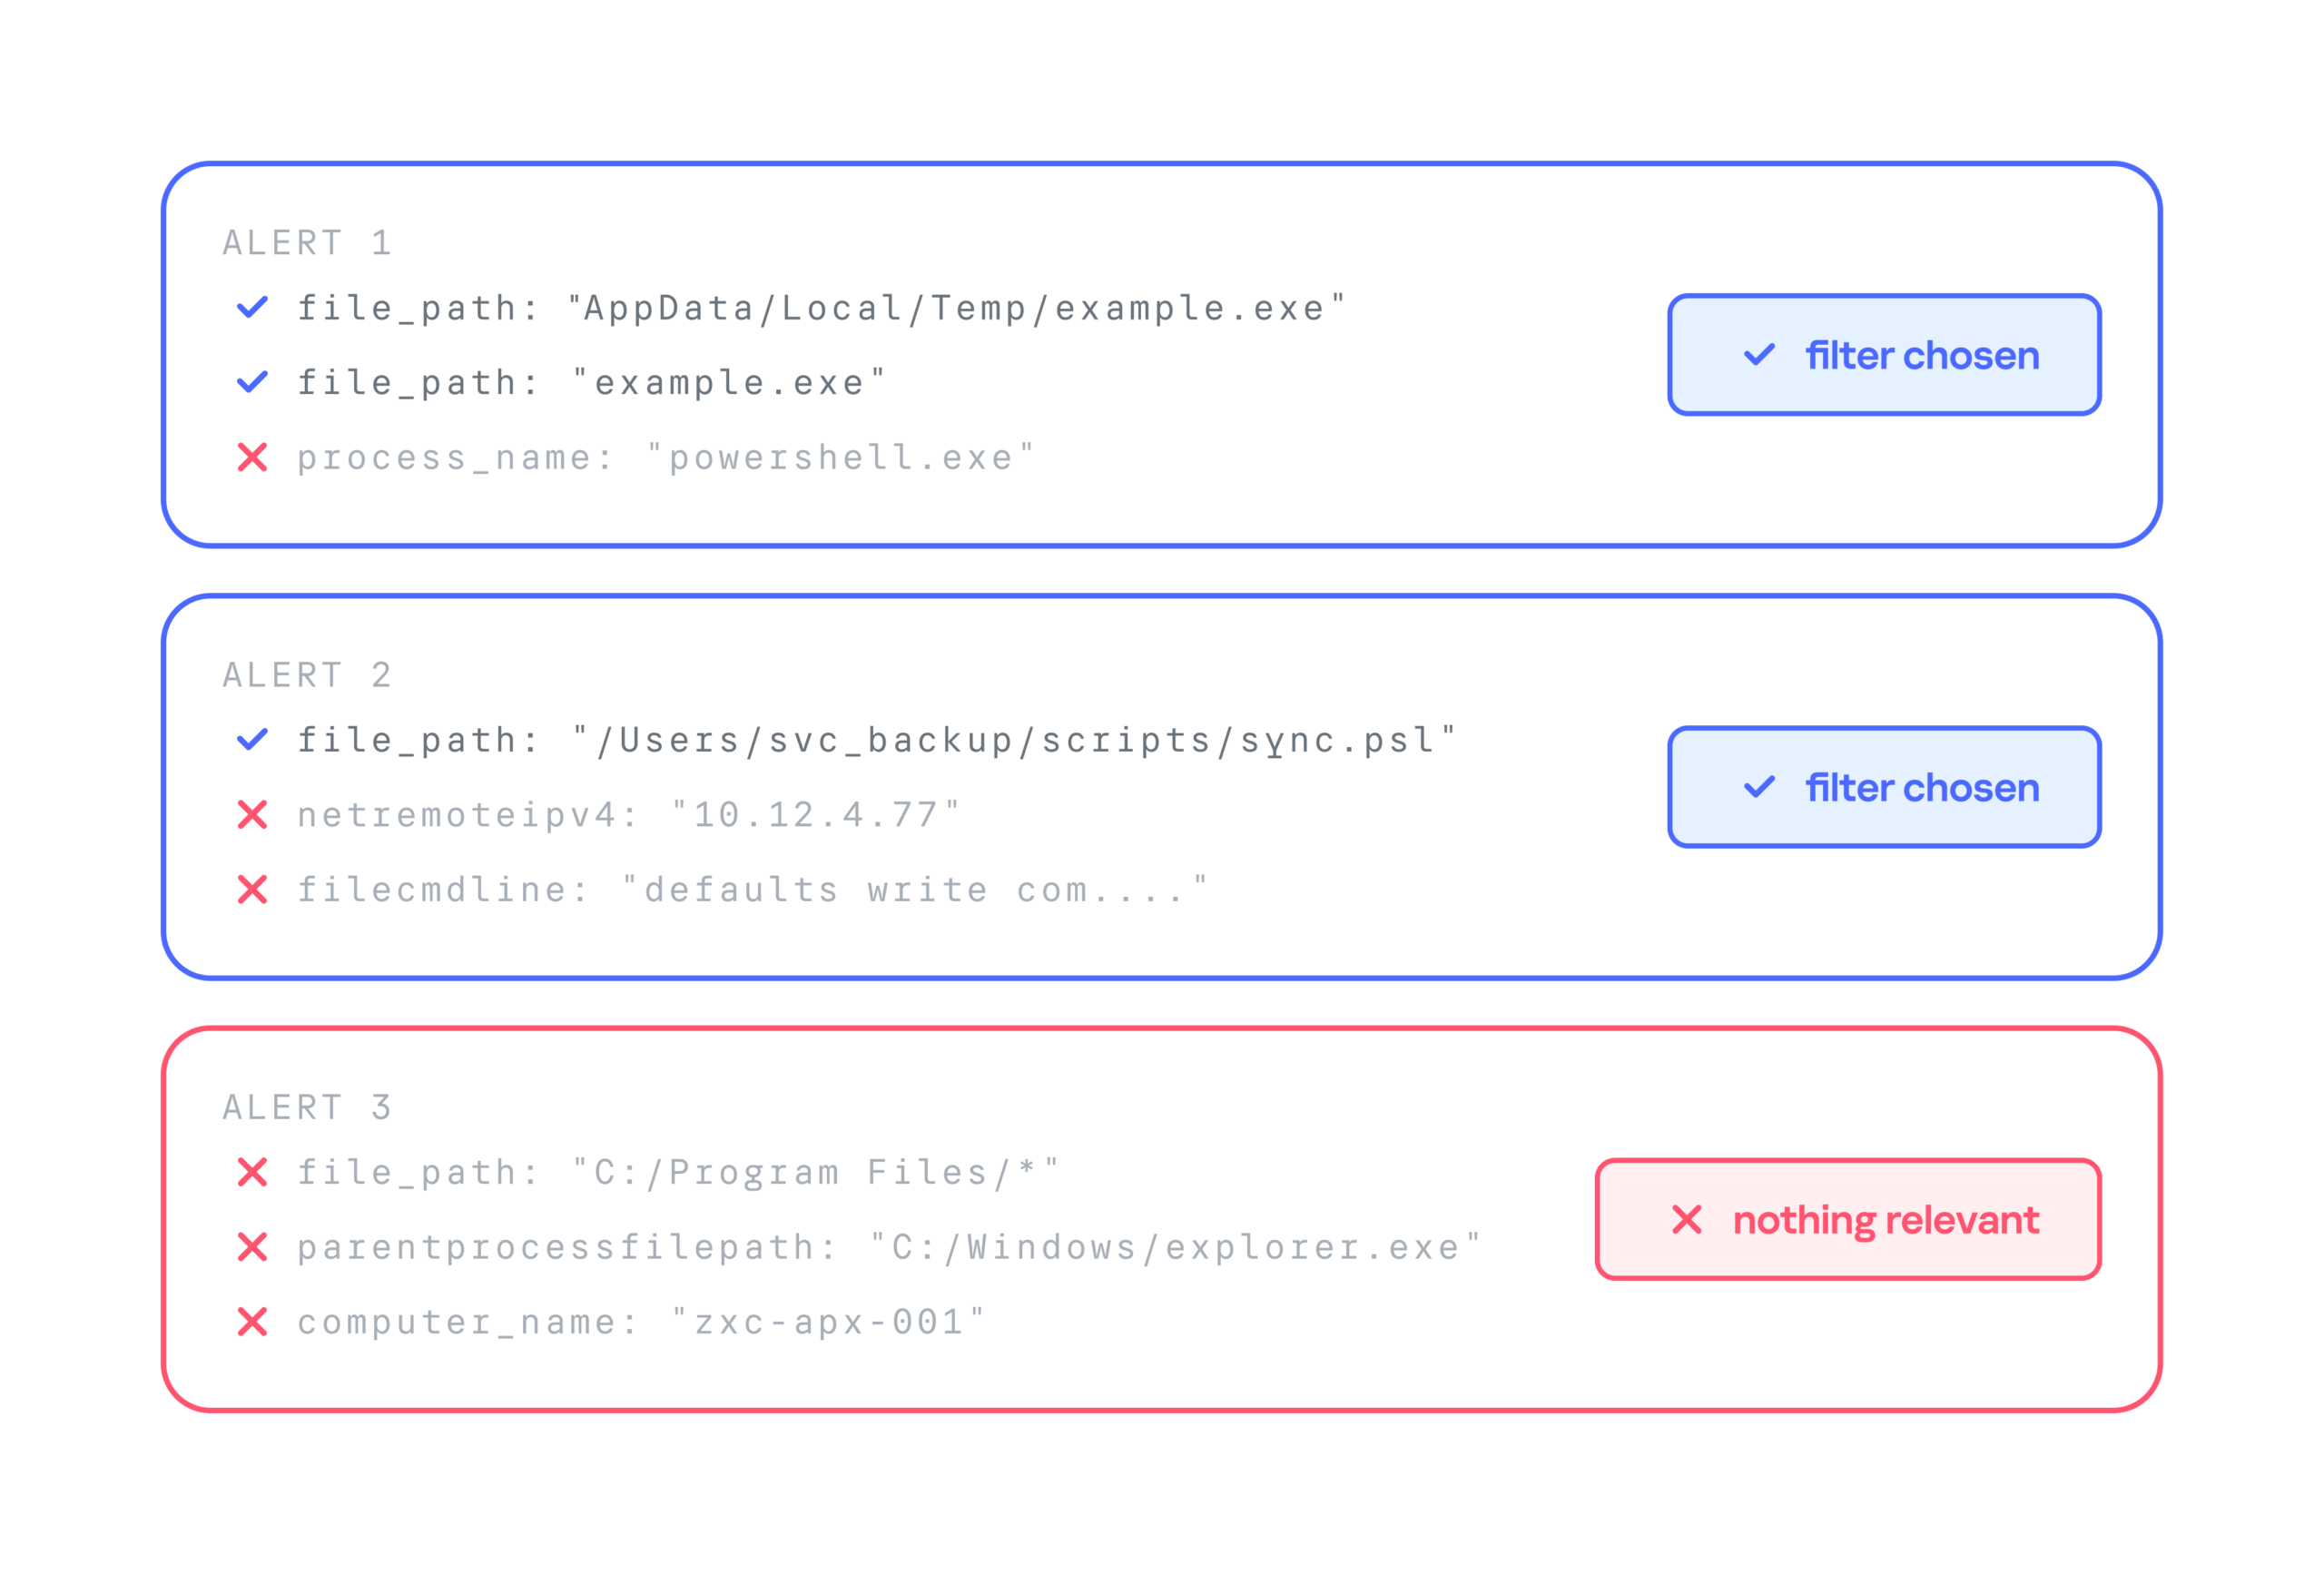
    • Approval rate. For each security alert, the system suggests three filters. If the analyst selects at least one of them, we count the generation as successful. For example, in the case below, the approval rate is 2/3.
    • False positive reduction rate (FP drop). This metric shows how much a filter helps reduce the number of false positives. It can only be measured over time, because we need to compare the number of false positive alerts received during a set period before and after the filter is deployed.

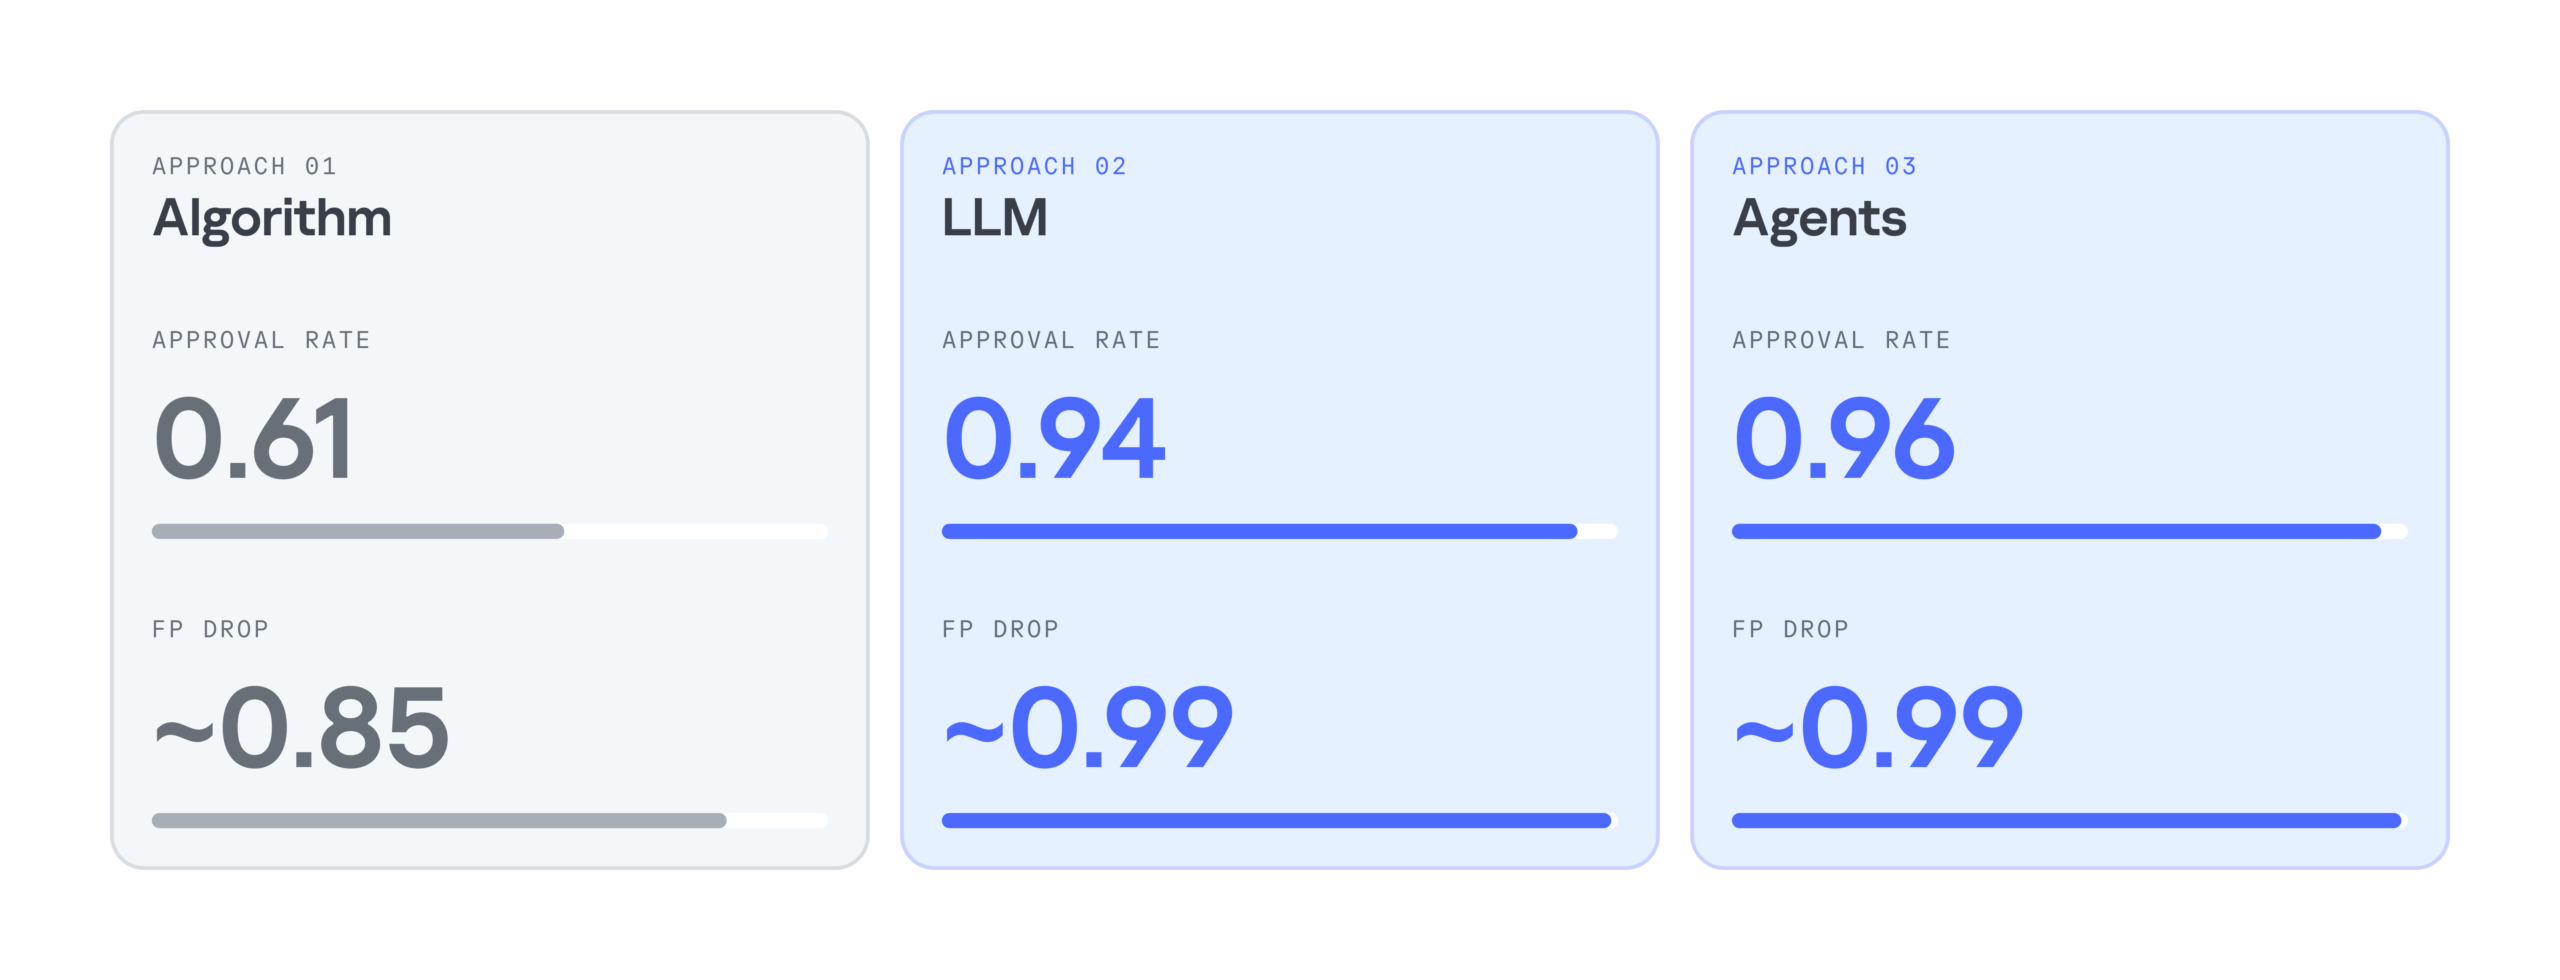
    Below is a comparison of the three filter generation approaches by these metrics:

    As the results show, LLMs significantly improve the efficiency of filter generation. At the same time, the LLM agentless and agent-based approaches perform almost identically. So we chose the simpler and faster option: an LLM with a single system prompt. As a result, we cut false positives by 99%, increased the number of filters generated per day by 28%, and made analysts’ alert handling 17% more efficient.

    Takeaways

    Practice has shown that filter generation can be automated effectively. We’ve looked at several options for automatically generating filters for false-positive security alerts: a purely algorithmic approach, an LLM-based approach, and an approach built on a group of LLM agents. All of them can generate valid filters and make the analyst’s work much easier, but each has its own pros and cons.

    The algorithmic approach scored lower on the evaluation metrics, but in two-thirds of cases, it still produces filters that satisfy the analyst. It works especially well when there’s already a set of similar events to filter out, meaning enough context has accumulated. The algorithmic generator can also be deployed in any environment. Both standalone LLM and multi-agent LLM approaches show high accuracy, and their results differ only slightly, so the slower agent-based approach looks excessive at this stage. If an LLM is available, the best option appears to be a single model that handles several stages of the generation cycle.

    Source: Securelist (Kaspersky GReAT) · 2026-10-30

  • Deploying AI agents securely: how Kaspersky products mitigate AI threats

    Deploying AI agents securely: how Kaspersky products mitigate AI threats

    Introduction

    AI agents and associated tooling are becoming increasingly common in corporate infrastructure. Agents can perform a range of actions with the user’s privileges, such as accessing data, running commands, and interacting with external services. This creates new security risks, especially when these tools are used without the security team’s oversight or well-designed policies.

    Detecting, tracking, and controlling AI agents is becoming one of the most pressing tasks for security teams today. We closely follow technological developments and continuously update our solutions to respond to new threats in a timely manner amid a rapidly changing technology landscape. This post describes new expertise built into Kaspersky products that helps counter the threats posed by the proliferation of AI agents. We approach this problem from several angles.

    First, you need to thoroughly understand the threat you are dealing with. To this end, we added profiles to the Kaspersky Threat Intelligence Portal that describe various AI agents and how attackers exploit them. At their core, AI agents are programs (processes) that run in the operating system on endpoints and can also launch other processes. This means that Endpoint Detection and Response solutions are among the key endpoint controls for this threat. These solutions detect the presence and launch of AI agents, track their activity, and identify potentially dangerous behavior. When needed, they also take action, such as stopping a suspicious process, blocking the activity, or isolating the host, to reduce the likelihood of an incident escalating. For this purpose, we developed specially adapted detection rules.

    You can use Kaspersky Endpoint Security, now also available as Kaspersky Next, to control and restrict the launch of AI agents. This solution uses two components to detect AI agents and control how they are used. Application Control categorizes the application processes launched on endpoints, and Web Control manages access to specific categories of web resources for users on endpoints.

    Finally, even harmless AI agents can contain malicious instructions (skills), such as those downloaded from unsafe external sources. Kaspersky Scan Engine analyzes installed applications to detect these threats and also checks LLM files for malicious code. Let’s take a closer look at these solutions and technologies.

    Tools from Anthropic and OpenAI take the top spots in the September 2026 ranking of AI agents by popularity among Kaspersky users. This list is based on telemetry from Kaspersky solutions. It shows the number of users who had the relevant AI vendors’ products installed at the time of the study.

    # AI product
    1 Claude
    2 Claude Code
    3 Codex
    4 OpenCode
    5 Zed
    6 Wispr Flow
    7 LM Studio
    8 ZCode
    9 Chatbox
    10 Cherry Studio

    The data shows that agentic systems, especially AI agents for software development, are the most popular AI applications. The TOP 10 also includes an application for running large language models locally (LM Studio) and a voice note-taking app (Wispr Flow).

    According to open sources, these are the most widely used AI services in 2026:

    # AI service
    1 ChatGPT
    2 Google Gemini
    3 Claude
    4 Grammarly
    5 DeepSeek

    While analyzing the most popular and widely used apps, our experts also noticed a sharp rise in vulnerable versions of AI-related software and services. From 2025 to date, more than 2500 vulnerabilities have been published:

    Number of published vulnerabilities in LLMs, AI tools, and plugins with similar functionality, 2025–2026 (download)

    * Data for previous quarters was updated and may differ slightly from previously published data.

    Application Control and Web Control

    To enforce the organization’s security policy for AI agents and other AI applications on the corporate network, Kaspersky products offer application control based on KL categories. These categories classify installed software and give you granular control over which approved applications can run in the organization.

    Application Control analyzes the processes launched on endpoints, tracking which AI agents are running in corporate systems at any given moment, on which hosts, and under which accounts. Application Control also shows how long a given program has been in use.

    This makes it easier for the Kaspersky Security Center (KSC) administrator to control applications. Administrators can use KL categories to allow or block AI agents inside the company for specific groups of employees.

    Here is what this functionality looks like to KSC administrators:

    KL categories available when configuring Application Control

    KL categories available when configuring Application Control

    For details on how to configure Application Control in KSC, follow this link.

    In Kaspersky Endpoint Security (KES), Application Control can operate in two modes:

    • Denylist. In this mode, Application Control lets users run any applications except those blocked by Application Control rules. This is the default mode.
    • Allowlist. In this mode, Application Control blocks users from running any applications except those explicitly allowed by Application Control rules.

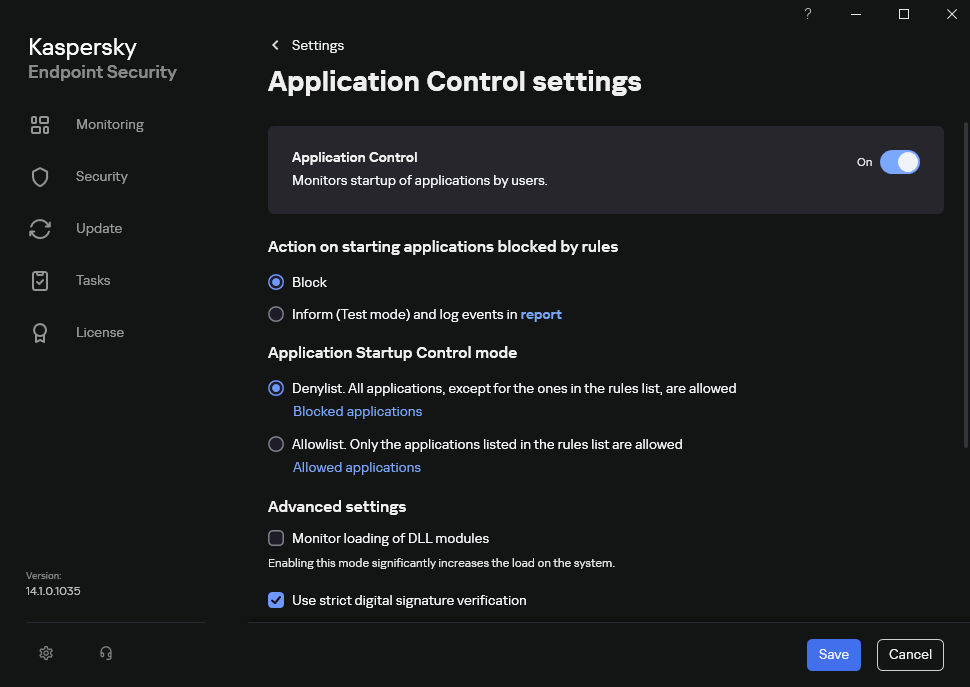
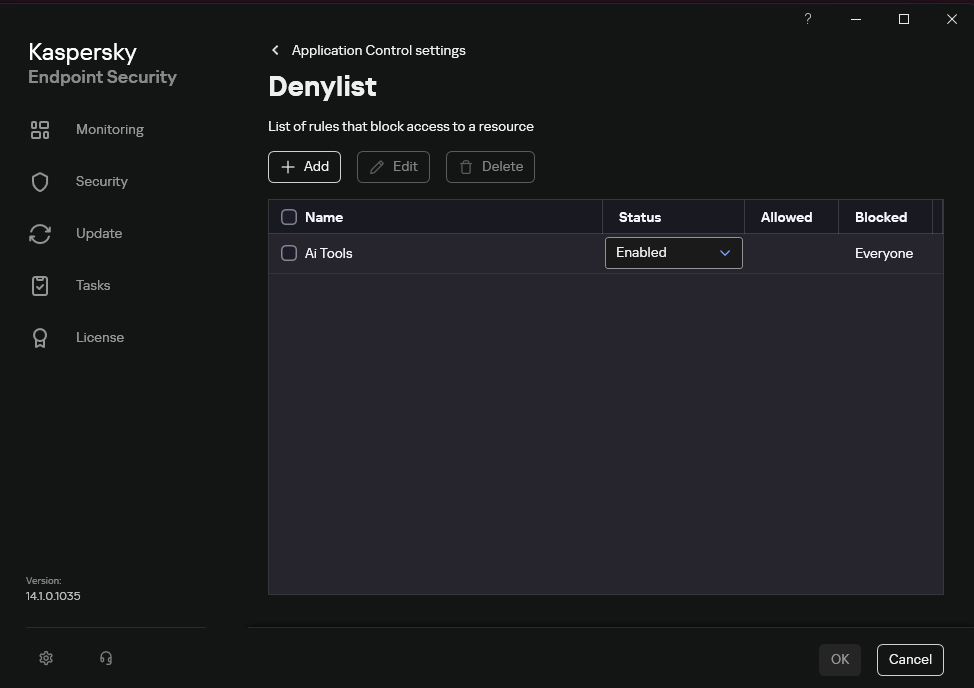
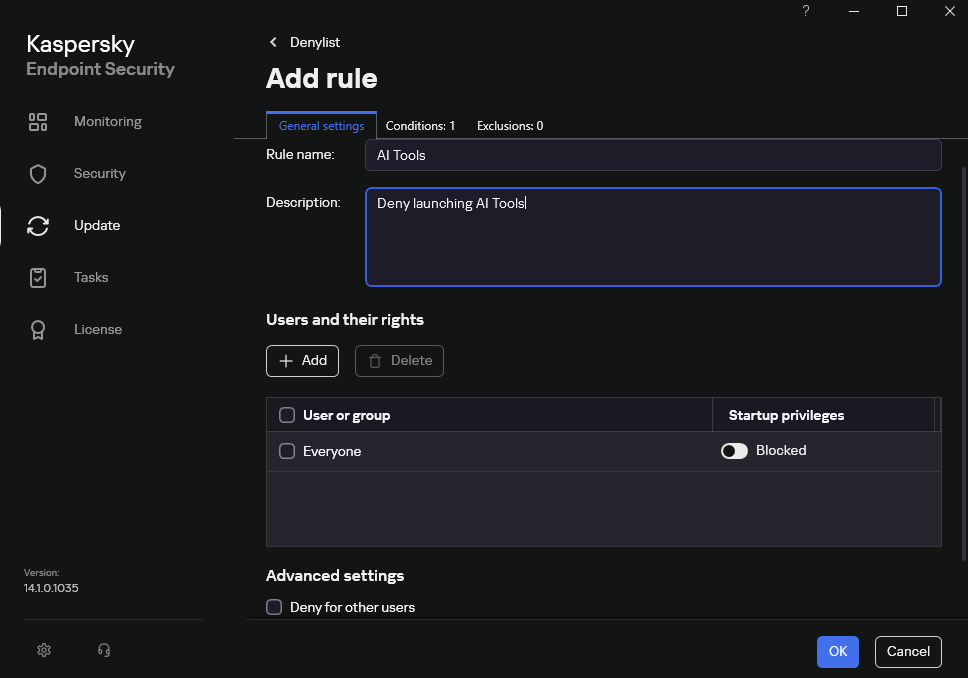
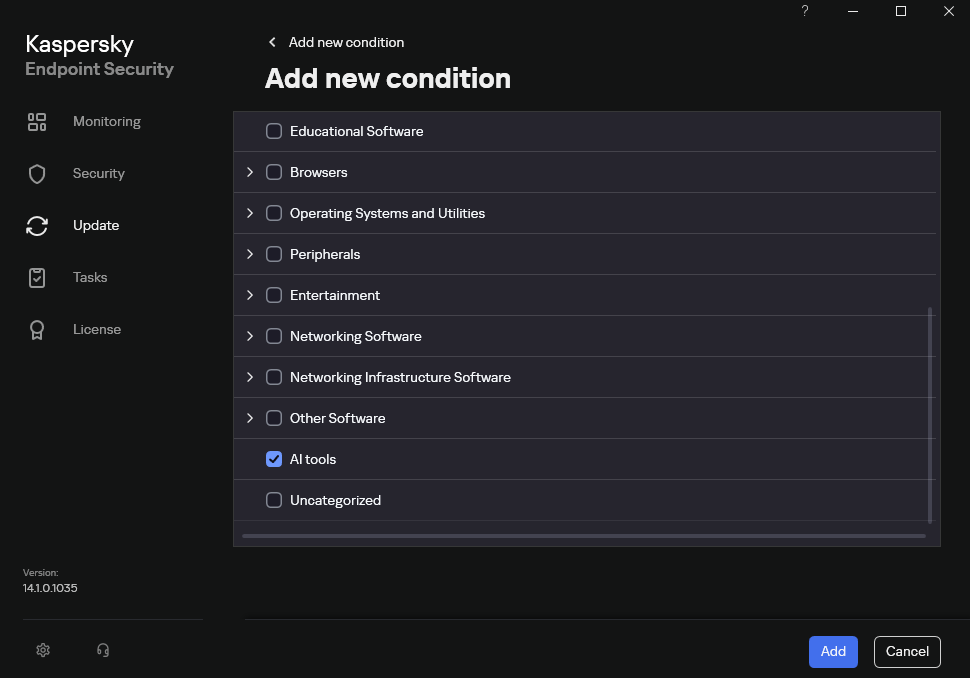
    Below are the steps to configure Application Control to block AI tools.

    Configuring Application Control for the AI Tools category in KES
    Configuring Application Control for the AI Tools category in KES

    Configuring Application Control for the AI Tools category in KES

    With this setup, when a user tries to launch an AI agent, they get a notification and the agent doesn’t start.

    KES notification about an attempt to launch an AI agent

    KES notification about an attempt to launch an AI agent

    For more on how to configure Application Control in KES, follow this link. Our public portal also lets you explore information on KL categories and the applications that fall under them, in particular details on how AI agents are categorized and how popular they are.

    AI Tools KL category

    AI Tools KL category

    The View applications drop-down list shows products for a specific vendor.

    Similarly, Web Control lets you manage user access to web resources. If a user tries to open a denylisted website, KES blocks access and shows a warning.

    KES notification about an attempt to access a prohibited web resource

    KES notification about an attempt to access a prohibited web resource

    When configuring access, the administrator can block websites that provide AI as a service.

    Website categories

    Website categories

    For more on configuring Web Control, follow this link. The help portal also provides information on website categories that can be assigned to resources to configure access control.

    Kaspersky Endpoint Detection and Response

    To an EDR solution, an AI agent is a regular process. It has its own executable, a tree of child processes, and network communications, all of which need to be monitored for suspicious activity. An attacker can use an AI agent as an automation tool. An AI agent installed as a legitimate user tool can also be leveraged in a ClickFix attack, where it executes a malicious instruction received from an untrusted source, such as a document, web page, or email. That said, unsafe actions by an agent do not always indicate an attack. There may be no malicious intent in the chain at all. An incident can result from what looks like an ordinary instruction from a user who doesn’t fully understand the consequences of having it executed. The mere fact that an agent was launched does not reveal whether it is being used in an attack. That is why Kaspersky EDR (KEDR) uses both conventional behavioral rules and rules written and adapted to detect AI tools. The latter identify risky agent actions and settings, and help determine which AI tool was involved in suspicious activity.

    Conventional KEDR rules detect the vast majority of familiar malicious techniques, including when performed by an AI agent. A suspicious PowerShell launch, persistence via Task Scheduler, or an attempt to steal credentials leaves clear, identifiable traces. These traces look the same no matter what initiated the actions. The rules analyze launch parameters, process relationships, affected files, network activity, and other telemetry events.

    For example, in a recent Armored Likho campaign, we found signs that AI had been used to create loader and dropper samples, which were later compiled with NSIS (Nullsoft Scriptable Install System). The key telltale artifacts were icons in the scripts and excessive comments on every function, which is uncharacteristic of human-written code. In addition, the group continues to generate new modules for its BusySnake Stealer and BusySnake RAT samples. For example, the attackers used AI to develop a module that runs multiple checks for virtual environment artifacts and calculates a score. Depending on the score, the sample either runs or exits with code 0. Even though the initial access samples, payloads, and their modules were AI-generated, the commands they execute via rundll32 and PowerShell are detected by the shell_creation_by_rundll32 and suspicious_powershell_cmd_or_script_spawning rules.

    So, for detecting an attack like this, it is not important who wrote the loader, the payload, or its modules: they are given away by the commands they execute, process relationships, and other traces of activity in the system. AI can be involved both in preparing the code and in carrying out the attack directly on the device.

    In the latter case, the attacker uses the agent to carry out their tasks and lets it choose and run the required commands within the privileges it has. For effective protection, it is critical to link suspicious actions back to the AI tool and the conditions under which it operates. In KEDR, several specialized rules handle this task.

    We have created separate rules for popular AI agents, ai_agent_*_access_to_sensitive_file_**, where * is the tool name and ** is the operating system. They generate alerts when an agent accesses files that contain credentials, tokens, or keys.

    The ai_agent_dangerous_execution_mode rule detects agents launched with auto-approval of all actions (so-called YOLO mode) or with the sandbox disabled. These settings do not indicate an attack on their own, but they let the agent perform dangerous actions without user confirmation.

    ai_agent_dangerous_execution_mode

    The suspicious_mcp_server_artifact rule triggers when MCP server scripts are created or modified in hidden, temporary, or cache directories. Attackers can place an MCP server in these locations to quietly connect it to the agent: through the MCP server, they can pass instructions to the agent, call third-party tools, and access the user’s data.

    suspicious_mcp_server_artifact

    The llm_api_access_by_unusual_apps rule generates an alert when an application on Windows, Linux, or macOS connects to the API of a known external LLM service, unless this activity falls under predefined exclusions. This helps spot model access by applications that do not normally behave this way.

    llm_api_access_by_unusual_apps

    Some Kaspersky EDR rules tag events for investigation but do not generate alerts. For example, the ai_agent_**_execution rules flag launches of known agents on Windows, Linux, and macOS. The local_ai_model_artifact rule records the creation or modification of AI model files in typical application, runtime, and cache directories. These events reveal AI tools on the device, including tools that run on local models and never call an external API.

    local_ai_model_artifact

    Kaspersky Threat Intelligence Portal

    AI agent profiles

    The Kaspersky Threat Intelligence Portal offers a large number of software profiles, including profiles of AI agents. You can sort them by the ai_ prefix:

    AI agent profiles on Kaspersky TIP

    AI agent profiles on Kaspersky TIP

    The profile of an AI agent such as Claude Desktop includes a detailed description of the software, the privilege level required to run it, supported platforms, and threat actor groups known to use it. It also lists tactics and techniques mapped to the MITRE ATT&CK framework, with descriptions of the procedures the tool can be used for.

    Claude profile on Kaspersky TIP

    Claude profile on Kaspersky TIP

    The description also lists ways to detect the software through standard system auditing mechanisms:

    • Windows: events from standard audit logs and Sysmon events
    • Linux: syscall audit events and Sysmon events
    • Network auditing: a set of protocols and the traffic generated by the software

    The detection section lists the main artifacts the software leaves in the system: command lines, possible launch parameters, names of the services and scheduled tasks it creates, and the key network artifacts.

    Detection section in the Claude profile

    Detection section in the Claude profile

    Hunt Hub

    In December 2025, the Kaspersky Threat Intelligence Portal added Hunt Hub (HH), a repository of detection rules. This is a unique Kaspersky project, and we developed it in response to growing market demand.

    This functionality is available in the Threat Landscape section of the portal. It gives analysts access to detection rules: their descriptions and their mapping to MITRE ATT&CK tactics and techniques, as well as to the associated cybercriminal groups.

    In the Hunt Hub section, customers can explore the detection logic of EDR, NDR, and NGFW products, including the logic for detecting AI agents.

    Rules in the Hunt Hub repository

    Rules in the Hunt Hub repository

    The rule card provides:

    • Detailed description
    • Rule’s severity level, confidence level, and alert format
    • Detection tips
    • Description of possible false positives
    • Platforms the rule can run on
    • Tactics, techniques, and sub-techniques covered by the rule
    • Groups that use the technique covered by the rule
    • Detection logic that shows what exactly triggers the rule
    Detection rule card in Hunt Hub

    Detection rule card in Hunt Hub

    Kaspersky Scan Engine

    Skills are a key component of the AI agent ecosystem. They’re prewritten sets of natural-language instructions that extend agent functionality. We previously covered the risks that malicious skills pose to agent users. A skill can require the usage of additional programs and services, come with helper scripts (for example, written in Python), or contain a malicious command embedded right in the instruction text. This means that adding skills to an originally harmless AI agent opens up several new ways for malicious code to enter the system. To prevent this, any skills obtained from external sources must be scanned. Kaspersky Scan Engine is well suited for this task. This is a cyberthreat detection and response solution that seamlessly integrates with various applications. It can detect malicious code in agent skills, associated scripts, and in files generated by running agents.

    Detection of a malicious agent skill in Kaspersky Scan Engine

    Detection of a malicious agent skill in Kaspersky Scan Engine

    Trained LLMs come in many formats. Some of them (PTH, PT, PKL, KERS, and others) also store parameters and weights (training datasets). These files can also contain malicious code, so it’s critical to scan them before running and using them. Kaspersky Scan Engine scans potentially dangerous LLM formats for infected data. It can deserialize and analyze models to detect malicious code regardless of model size.

    Detection of an LLM with malicious code in Kaspersky Scan Engine

    Detection of an LLM with malicious code in Kaspersky Scan Engine

    Conclusion

    AI agents are rapidly making their way into corporate environments: they help employees work faster and take on a wide range of tasks, but they also open up new opportunities for attackers. To take advantage of this technology without compromising security, organizations need to build multi-layered protection and minimize risks. A range of Kaspersky solutions can help with this:

    • Kaspersky TIP keeps you up to date on current scenarios in which attackers use AI agents, and its Hunt Hub section provides rules for detecting suspicious AI agent activity.
    • Kaspersky EDR detects AI agents in the infrastructure and monitors their activity on endpoints. If it detects potentially dangerous actions, the product can log the event, notify the SOC, and take response actions, such as stopping the process or isolating the host.
    • Application Control in Kaspersky products can fully restrict the use of AI agents within the company by using application categorization. The Web Control component can restrict access to AIaaS web resources.
    • Kaspersky Scan Engine can be integrated into various company processes to detect malicious code in any files, including AI agent skills and LLMs.

    When companies combine the tools described above in a comprehensive approach, they can adopt AI agents in an informed way: with an understanding of the associated risks and effective means of minimizing them.

    Source: Securelist (Kaspersky GReAT) · 2026-10-26